Claude Opus 4.6 vs Grok 4.5: Coding Price Clash
Claude Opus 4.6 wins the coding trust fight today, but Grok 4.5 lands the cleaner price punch. If you need benchmark-backed coding confidence, pick Claude. If your workload is high-volume generation where output cost matters more than leaderboard proof, Grok 4.5 is the cheaper bet.
Coding benchmarks: Claude has the harder evidence
The current July 2026 benchmark chatter puts Anthropic’s Claude Opus line at 93.9% on SWE-Bench and 94.6% on GPQA Diamond, with Claude Opus 4.6 specifically named among the coding leaders. That’s a serious card to bring into the ring.
Grok is in the same conversation, but the supplied material names Grok 4 among coding leaders, not Grok 4.5 with a quoted score. So I’m not giving Grok 4.5 a trophy it hasn’t earned in the numbers here. It may be strong, but Claude Opus 4.6 has the cleaner receipts.
Price: Grok 4.5 swings back hard
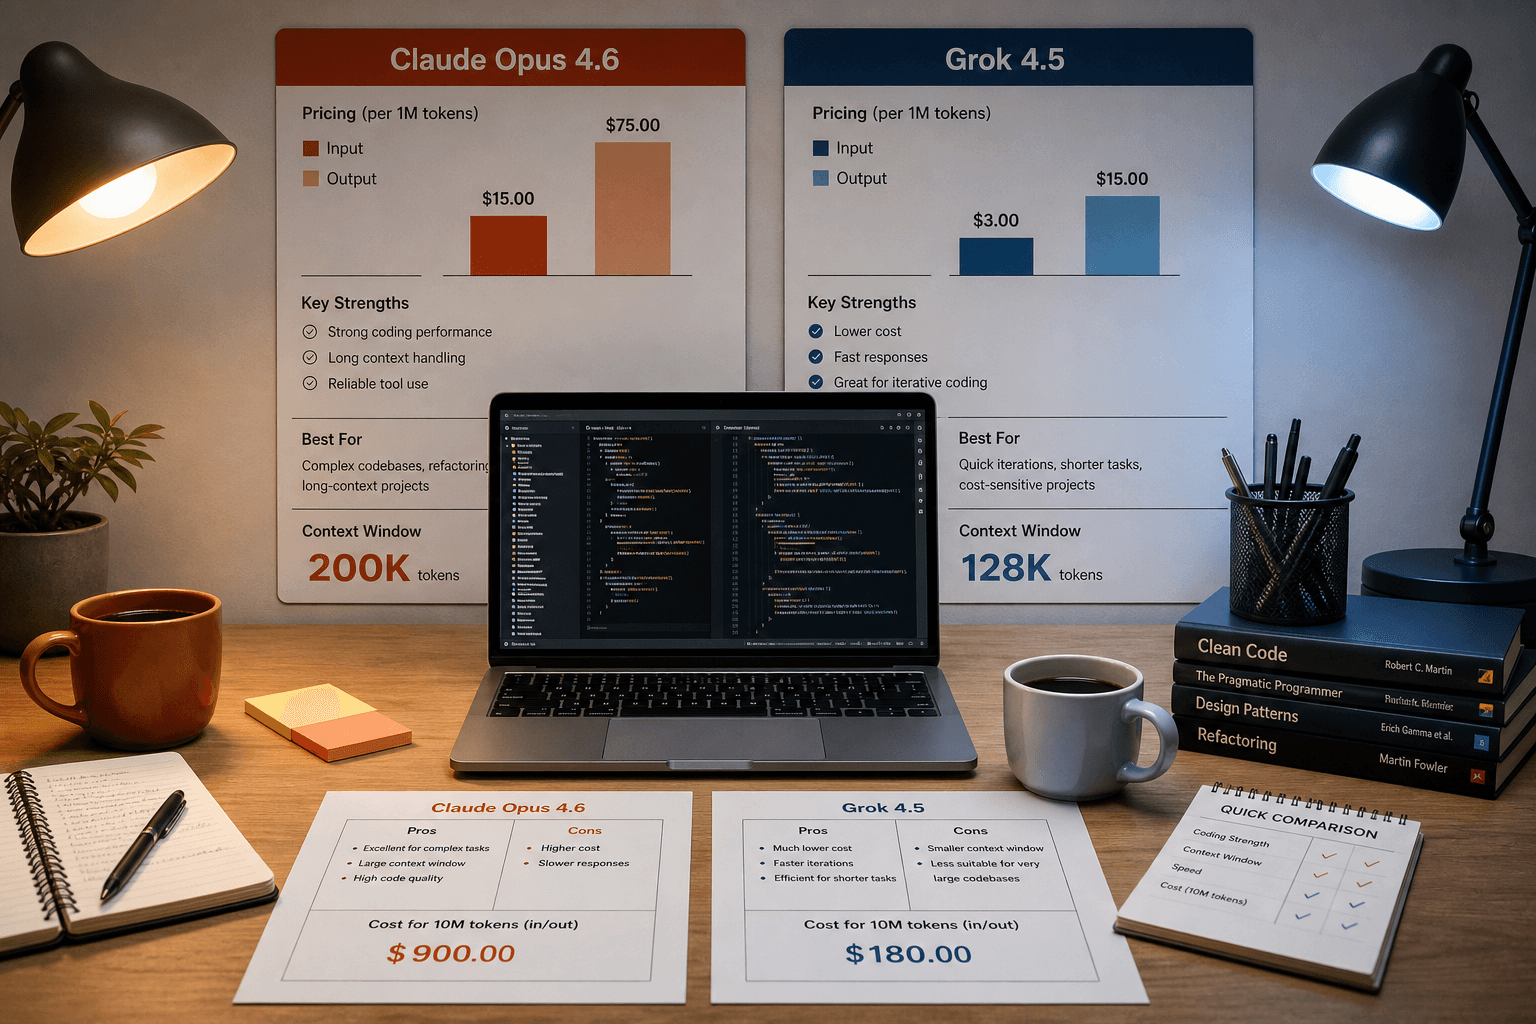
Here’s where the bout changes tempo. Claude Opus 4.6 costs $5.00/1M input tokens and $25.00/1M output tokens. Grok 4.5 costs $2.00/1M input tokens and $6.00/1M output tokens.
That’s not a small gap. On output-heavy coding agents, test generation, refactors, and documentation passes, Grok 4.5 is $19.00 cheaper per 1M output tokens. Claude may be the steadier technical finisher, but you pay for every round.
Practical use: confidence versus throughput
Claude Opus 4.6 is the better fit when correctness pressure is high: production code review, bug hunts, architecture reasoning, and tasks where a failed answer burns engineer time.
Grok 4.5 makes more sense for broad iteration: drafts, boilerplate, log analysis, internal tools, and coding workflows where humans still review aggressively and token volume is the main enemy.