Claude Opus 4.8 vs Gemini 3.1 Pro Preview: Code or Reason
My card has Claude Opus 4.8 ahead for serious coding, but Gemini 3.1 Pro Preview wins the value round for reasoning-heavy work. The gap isn’t subtle on SWE-bench Verified: Claude lands 88.6% while Gemini posts 54.2%. But Gemini answers back hard on price at $2.00 in and $12.00 out per 1M tokens.
Coding: Claude throws the heavier hands
If your workload is repo repair, agentic coding, or bug-fix automation, Claude Opus 4.8 is the cleaner pick. The supplied benchmark table has it at 88.6% on SWE-bench Verified, compared with 54.2% for Gemini 3.1 Pro Preview. That’s not a tiny leaderboard shuffle; that’s a full-round knockdown.
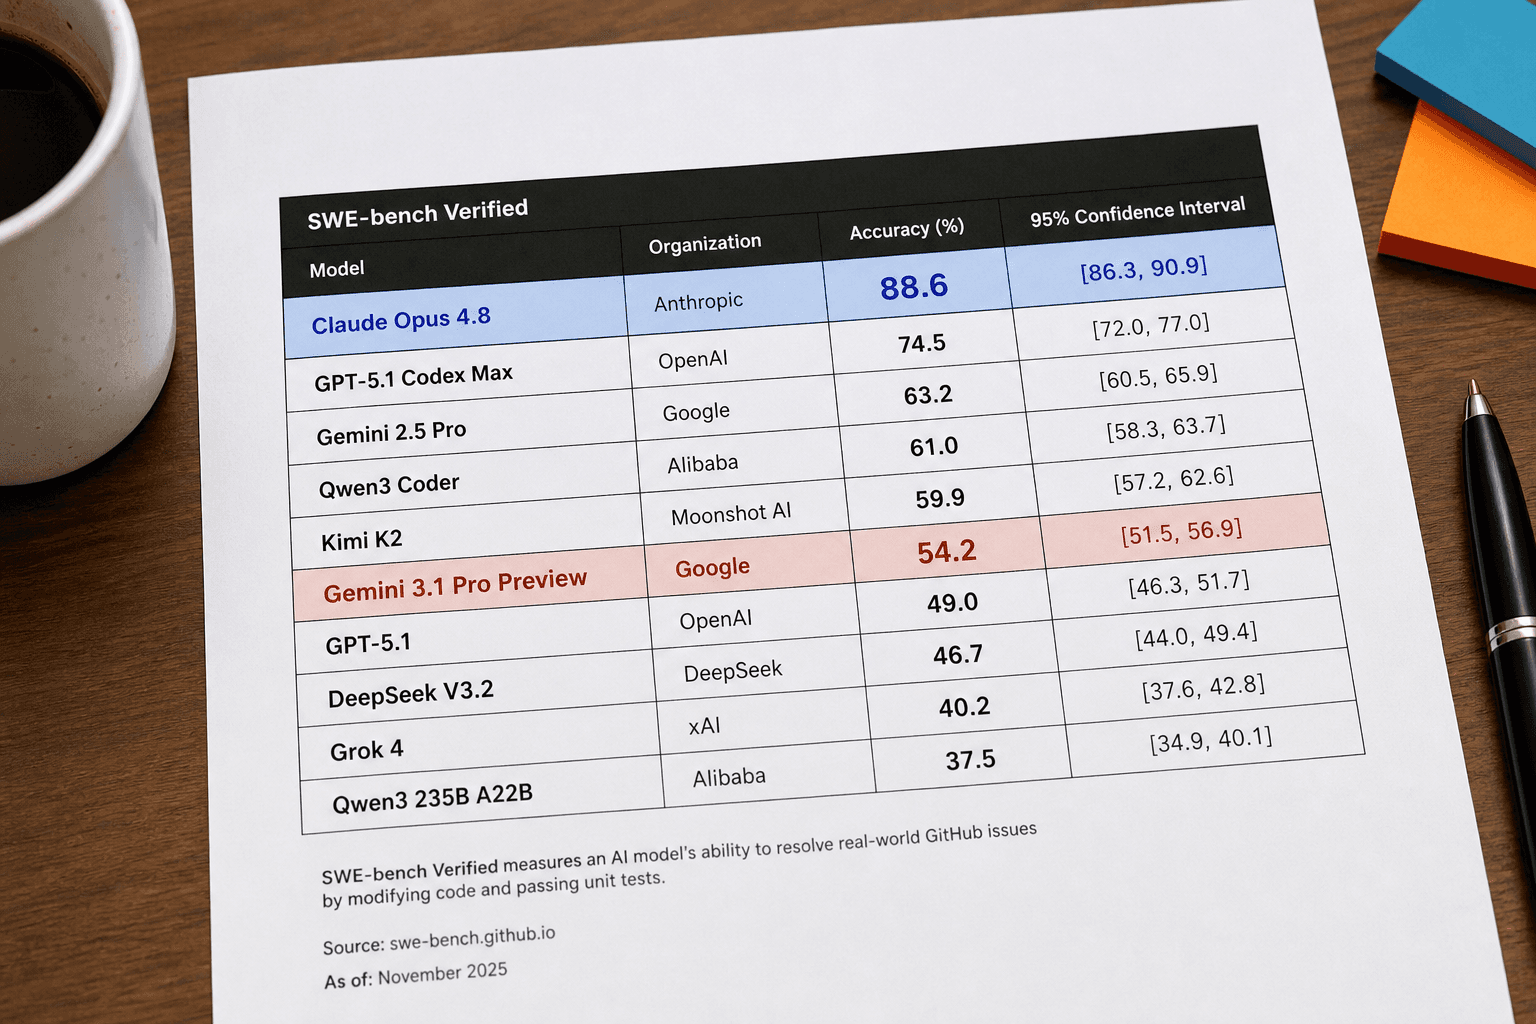
Claude also leads the overall LLM Stats ranking at 67.9, ahead of GPT-5.5 at 62.9 and Claude Opus 4.7 at 60.5. Gemini’s coding number doesn’t make it weak, but against Claude Opus 4.8, it’s clearly fighting uphill.
Reasoning and price: Gemini makes the math hurt
Here’s where Gemini 3.1 Pro Preview gets dangerous. The current comparison notes say Gemini 3.1 Pro leads reasoning benchmarks. No exact reasoning percentage was provided, so don’t oversell it — but the direction is clear.
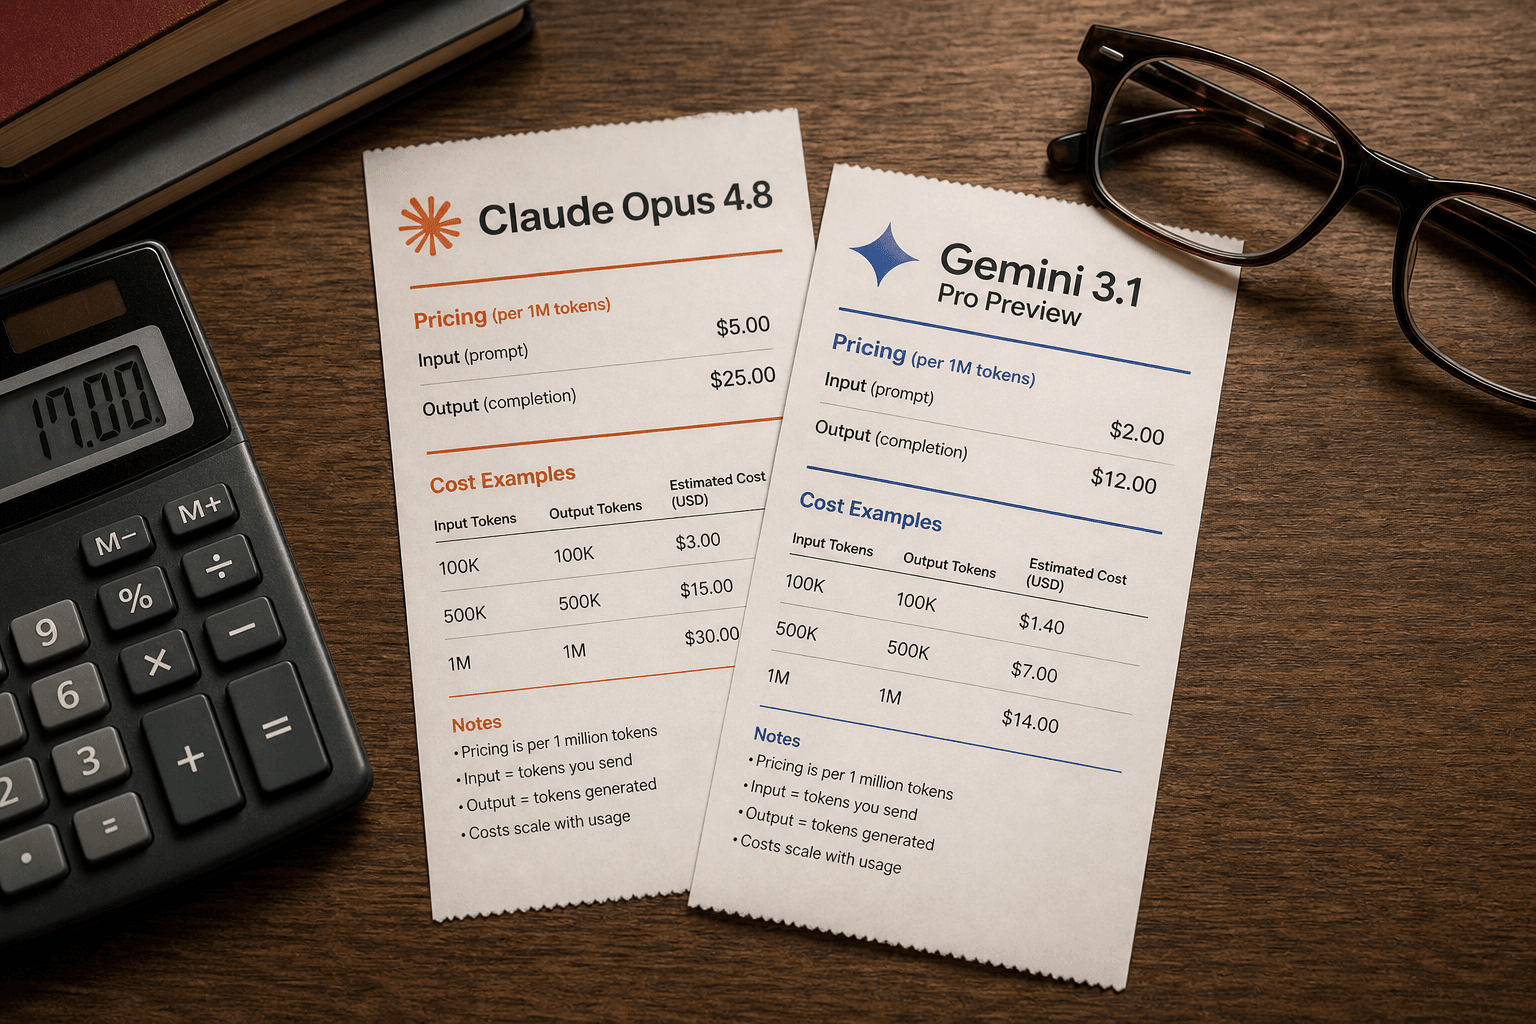
Then the bill arrives. Claude Opus 4.8 costs $5.00/1M input tokens and $25.00/1M output tokens. Gemini 3.1 Pro Preview costs $2.00/1M input and $12.00/1M output. That’s less than half the input price and less than half the output price. For long reasoning chats, summaries, planning, and analysis, Gemini’s corner is smiling.
Context: don’t pretend every point matters
The live benchmark notes also say top models are tightly packed, with the top 15 separated by as little as 3 percentage points across benchmarks. So outside coding, the smarter move is matching model to workload instead of worshiping rank.