Claude Fable 5 vs Grok 4.5: Premium Code or Cheap Muscle
Verdict first: Claude Fable 5 is still the sharper frontier pick when quality is the whole fight, but Grok 4.5 is the value bruiser builders should take seriously. At $2.00 in and $6.00 out per million tokens, it makes Claude’s $10.00/$50.00 pricing feel heavyweight in all the expensive ways.
Coding and reasoning: different scorecards, real gap
Claude Fable 5 lands the cleaner headline numbers: 95.0% on SWE-bench Verified and 94.6% on GPQA Diamond. That’s elite, no dancing around it. If you’re asking for hard repo fixes, high-stakes reasoning, or fewer second-round retries, Claude Fable 5 is the safer corner.
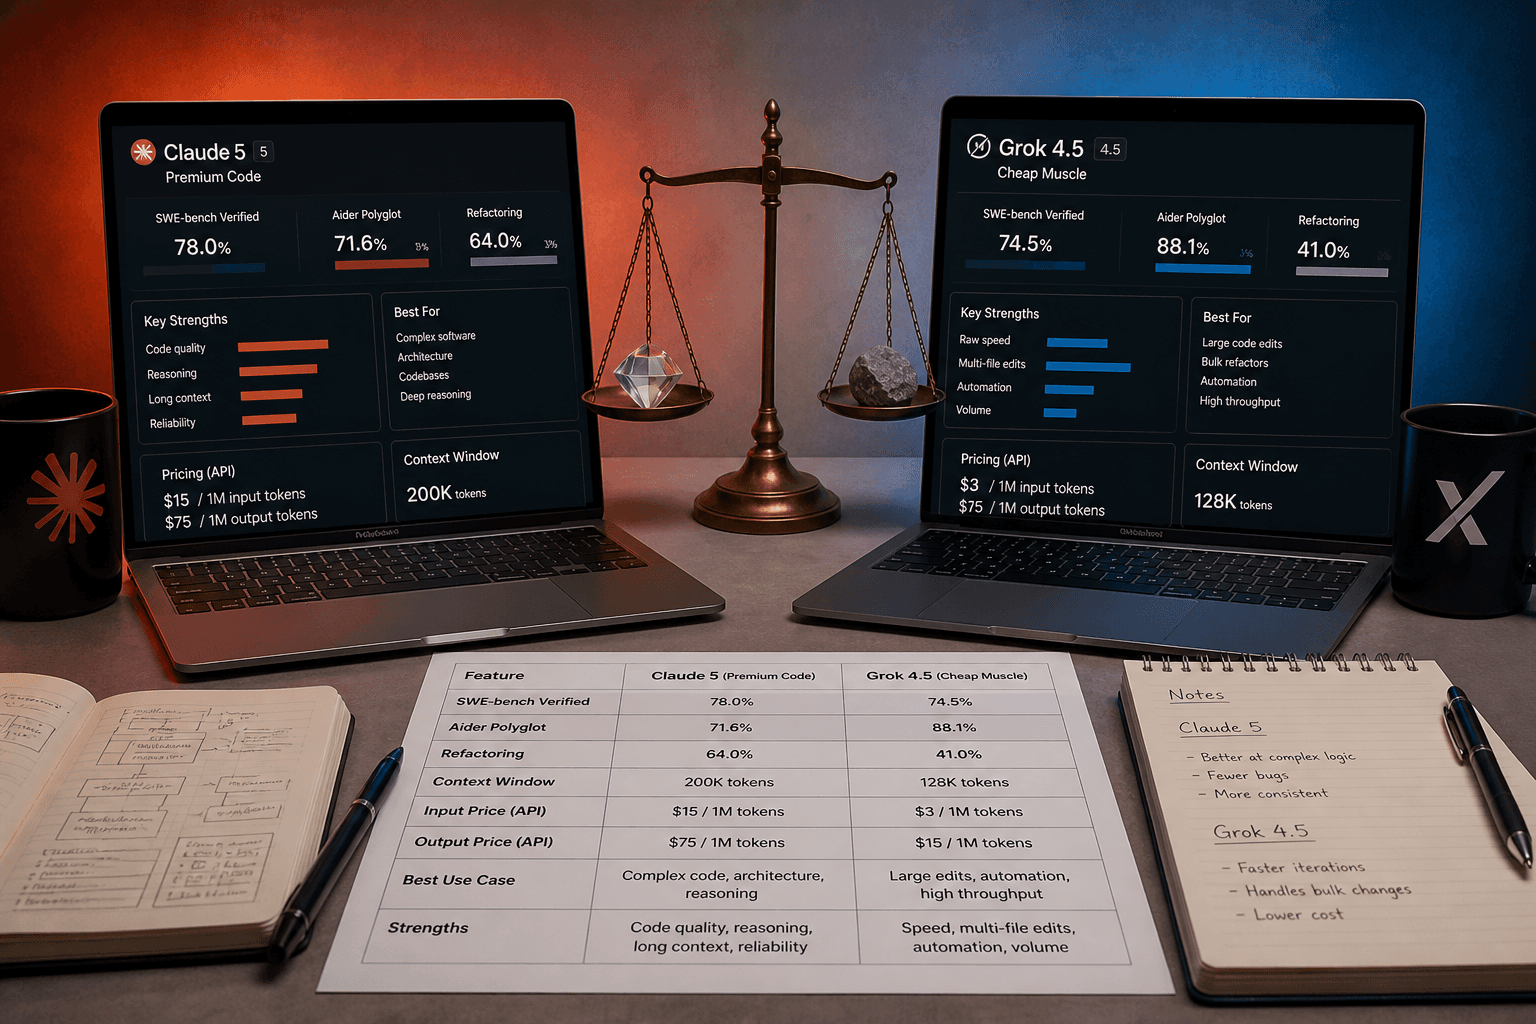
Grok 4.5’s cited number is 64.7% on SWE-bench Pro, which isn’t the same benchmark as SWE-bench Verified, so don’t compare those scores like-for-like. Still, 64.7% on a tougher-sounding coding track at this price is why people are arguing about it. It’s not stealing the belt, but it’s throwing volume.
Price: Grok 4.5 hits the ribs
Here’s where the bout gets loud. Claude Fable 5 costs $10.00 per 1M input tokens and $50.00 per 1M output tokens. Grok 4.5 costs $2.00 per 1M input and $6.00 per 1M output.
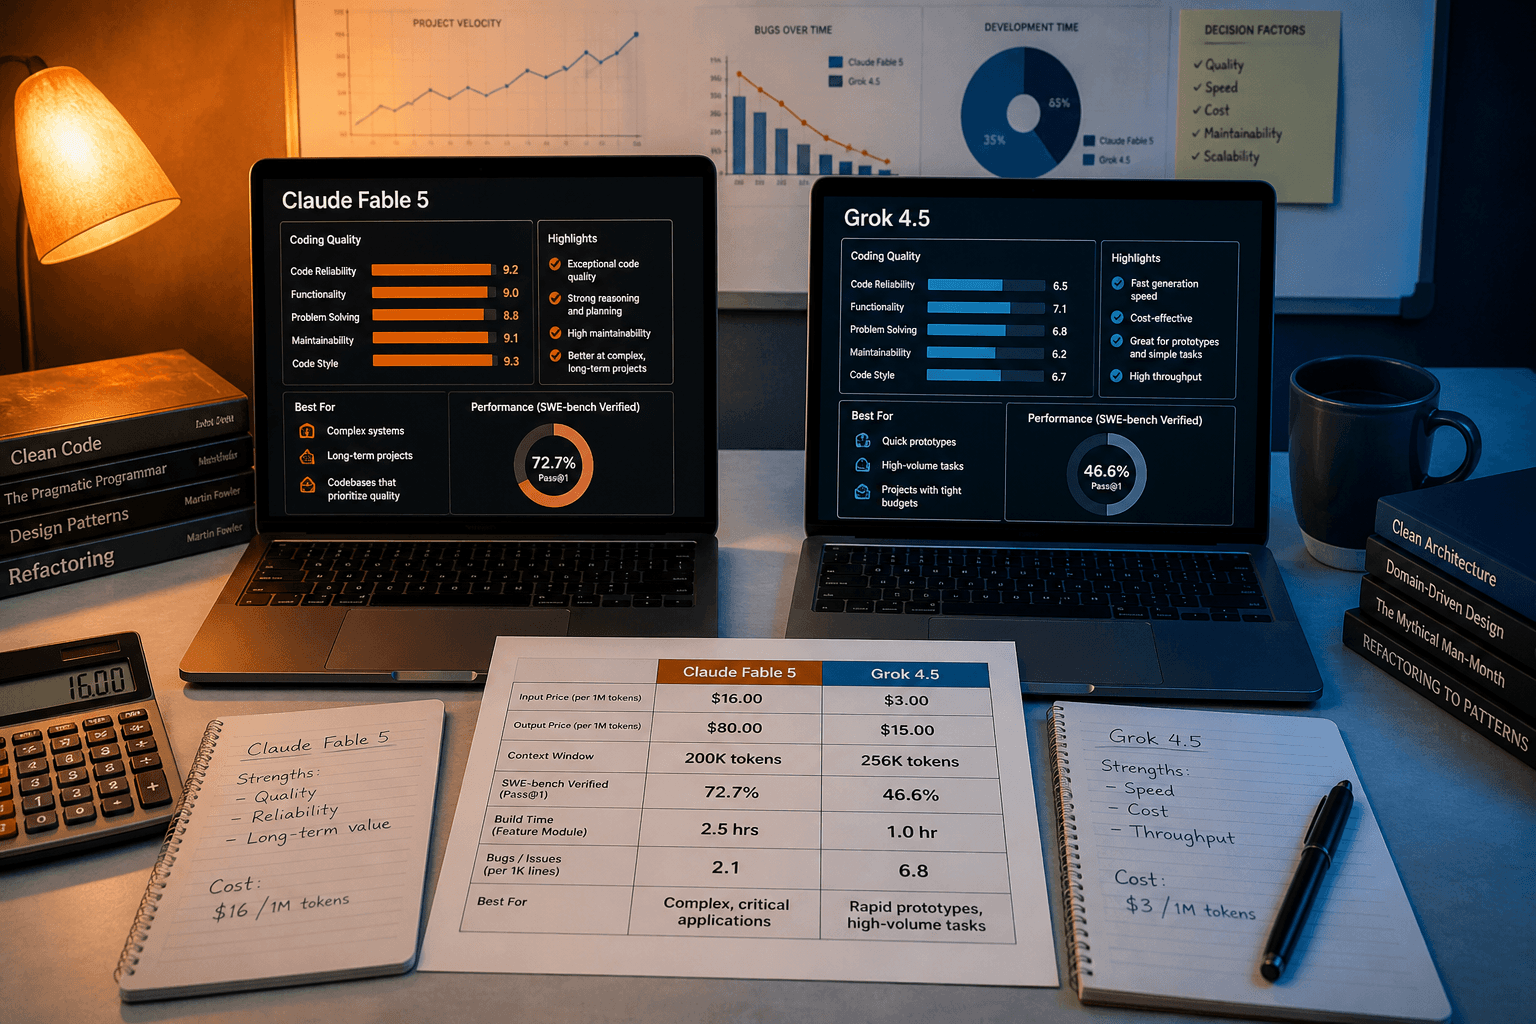
That means Claude is 5x the input price and about 8.3x the output price. For chatty agents, code review loops, support bots, and batch analysis, output tokens are where budgets bleed. Grok 4.5 doesn’t need to beat Claude outright to win those workloads; it just needs to be good enough often enough.
Market timing: narrow gaps raise the pressure
The 2026 frontier is tight: current search results describe the top 15 models as separated by as little as 3 percentage points across benchmarks. That’s why cost is now landing more punches than tiny leaderboard moves.