DeepSeek R1 vs Llama 4: Code Smarts vs Book Smarts
DeepSeek R1 beats Llama 4 at coding but Llama 4 wins the knowledge quiz. If your job is shipping code, pick DeepSeek. If you need broad facts and reasoning across many topics, Llama 4 is the safer bet. Neither is a clean sweep, and the gap matters more than the hype.
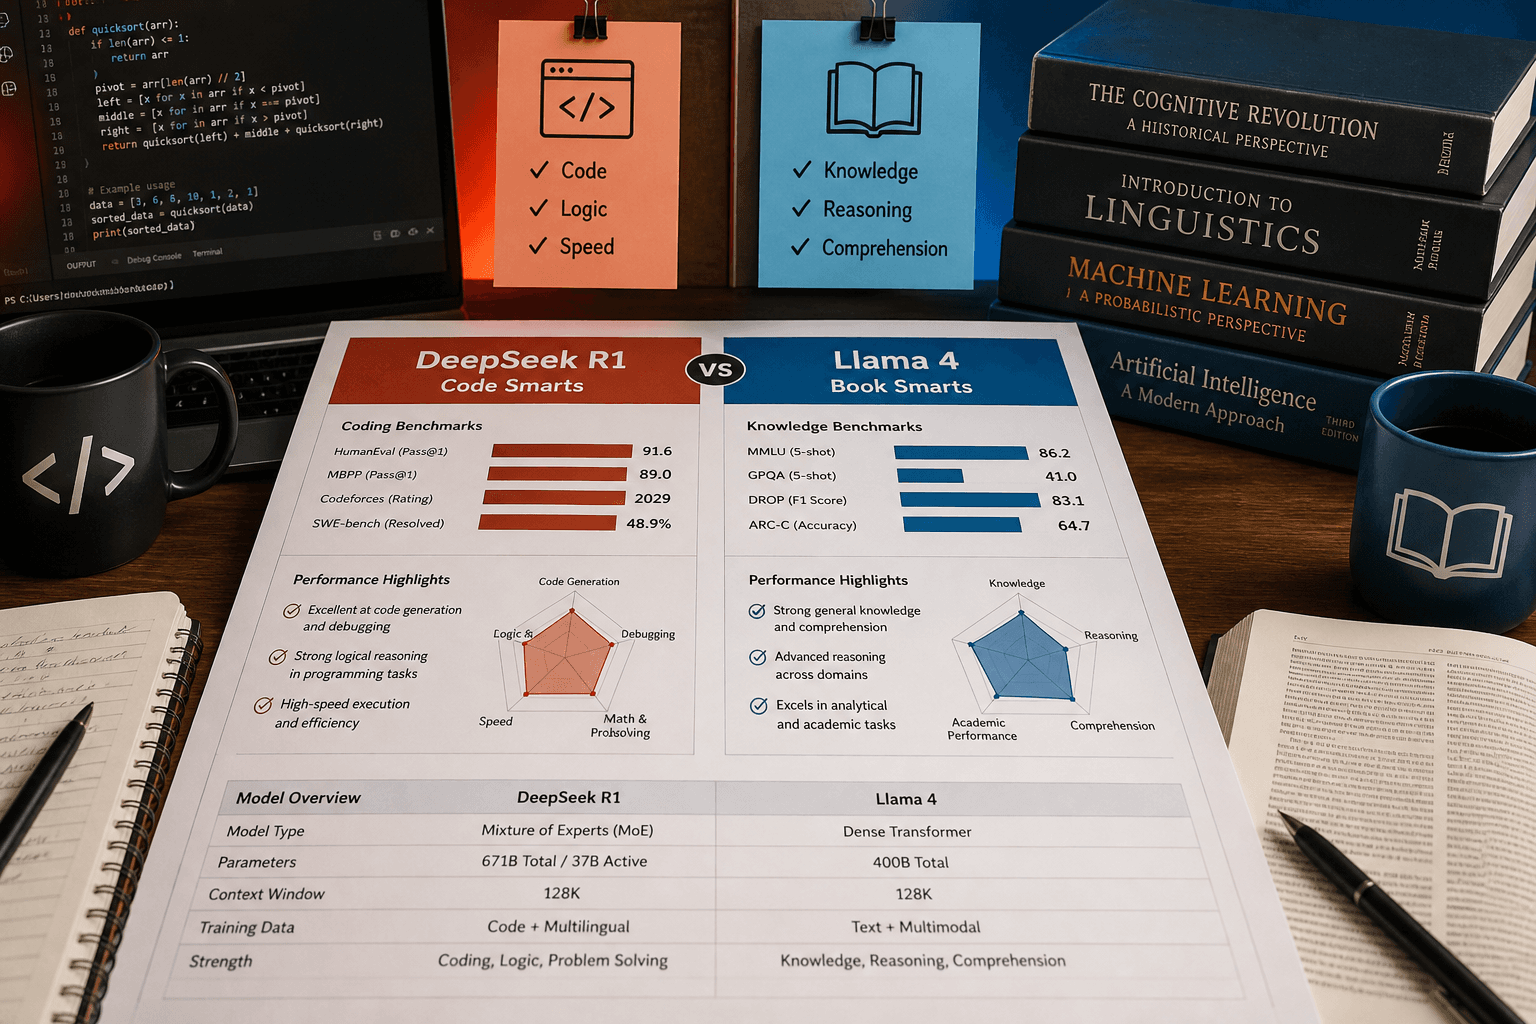
Coding: DeepSeek takes it
On HumanEval, DeepSeek R1 scores 74.6% while Llama 4 trails at 67.2%. That's a real seven-point lead, not noise. For code generation tasks, DeepSeek R1 is more likely to produce working solutions out of the box, which means fewer debugging loops and less time wasted in review.
Knowledge and reasoning: Llama fights back
Flip to MMLU and Llama 4 hits 82.5% versus DeepSeek R1's 78.2%. That's a four-point edge in general knowledge and reasoning. If your prompts lean on facts, definitions, or multi-step reasoning across domains, Llama 4 holds up better. So the pick depends on what you actually feed it.
The catch: strengths are narrow
Neither model dominates across the board. DeepSeek R1's coding edge doesn't make it a better assistant for general questions, and Llama 4's MMLU lead won't save a bad code review. These are specialty tools, so match the model to the workload instead of chasing a single benchmark.
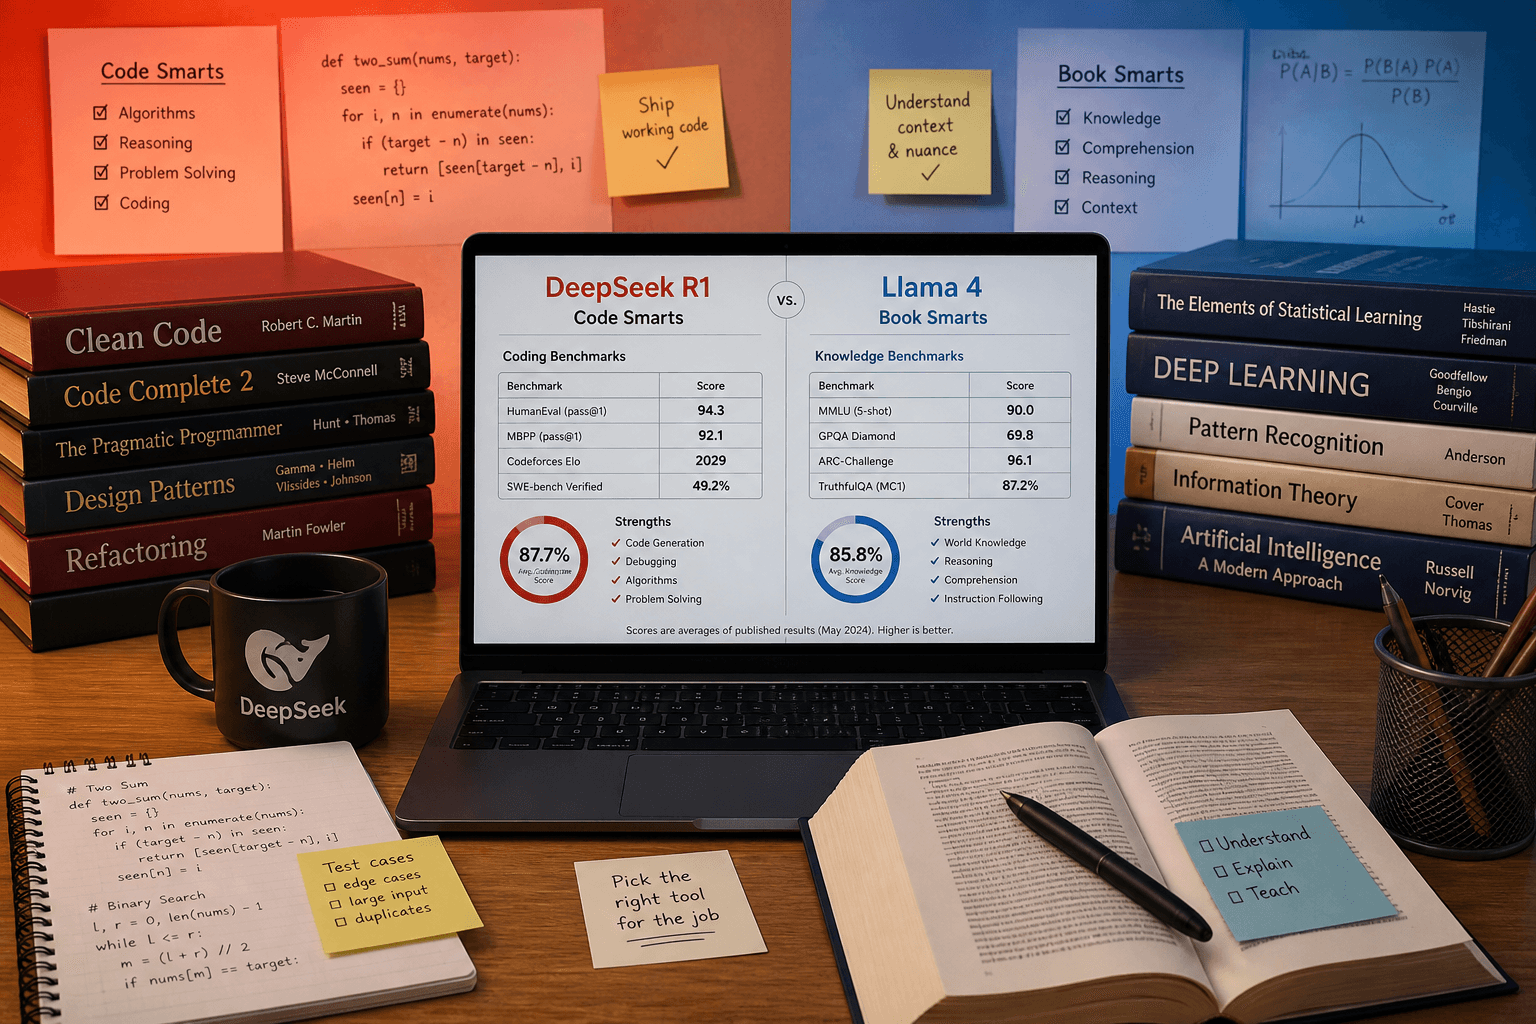
Verdict: which one should you pick?
Pick DeepSeek R1 if your work is mostly code generation and you want fewer failed attempts. Pick Llama 4 if you need broad factual accuracy and everyday reasoning. If your workload mixes both, test on your own prompts before committing — the benchmark split is too close to call a universal winner.