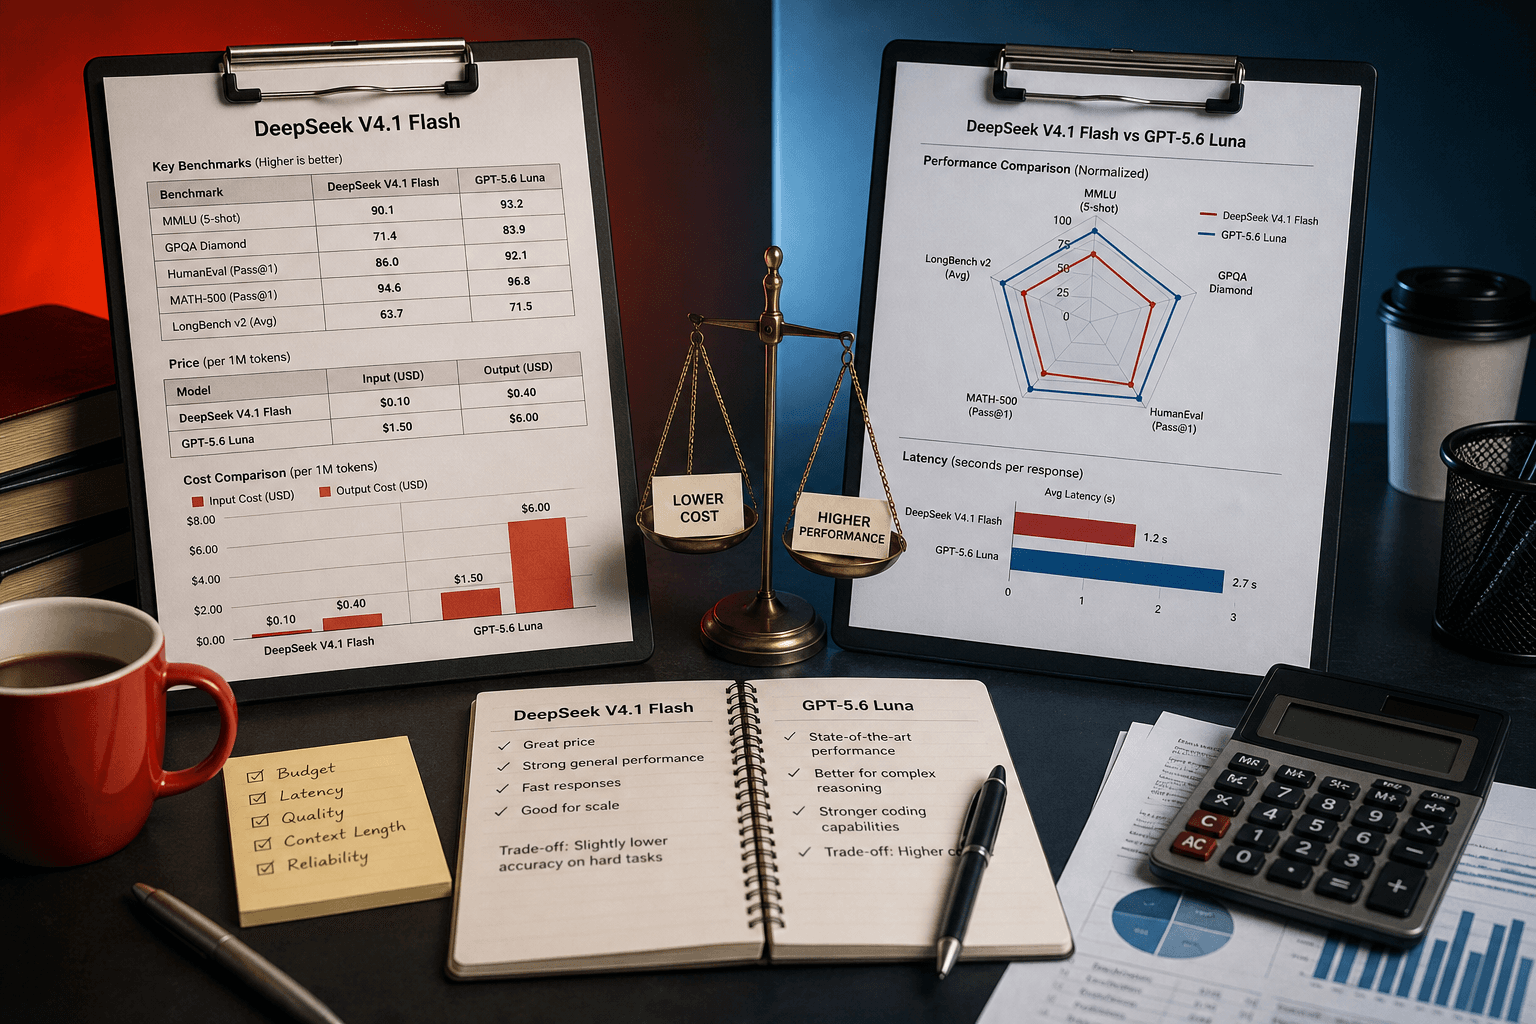
DeepSeek V4.1 Flash vs GPT-5.6 Luna: Cheap Brains, Real Trade-Offs
DeepSeek V4.1 Flash is the better pick if you're doing red-team or security work and need raw, steerable output for pennies — but GPT-5.6 Luna wins for general reasoning and reliability per dollar. They cost nearly the same, sit at the bottom of the price table, and force very different compromises. Here's the breakdown.
Price and raw cost
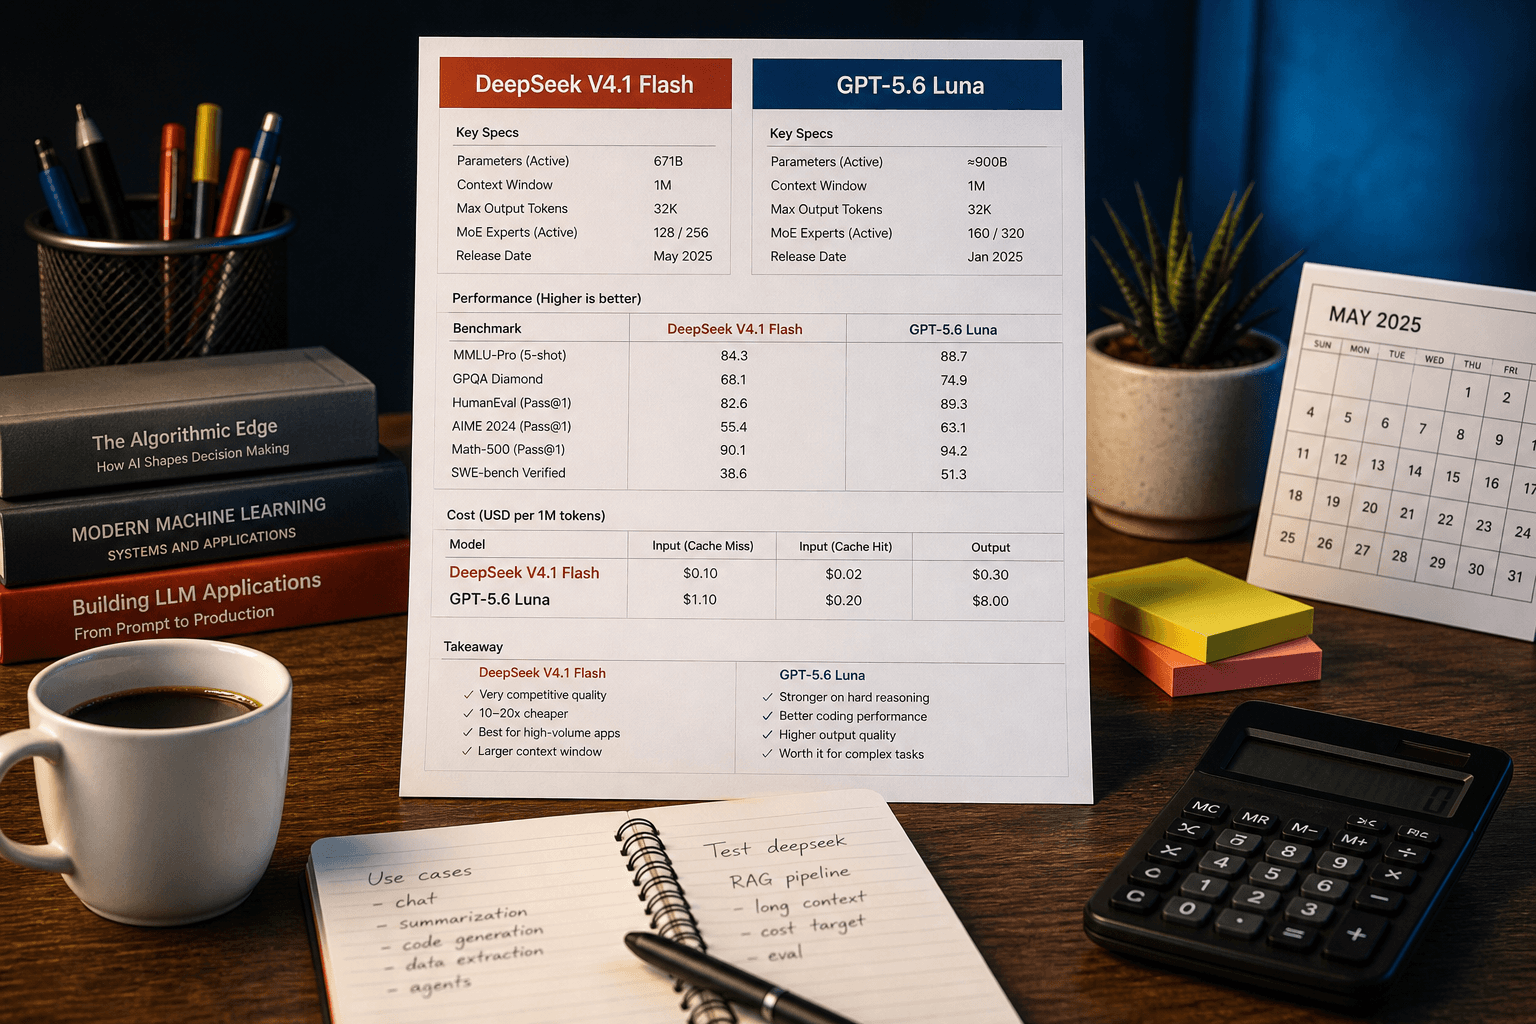
No contest on paper. DeepSeek V4.1 Flash runs $0.30 per 1M input tokens and $1.20 per 1M output tokens. GPT-5.6 Luna undercuts the input side at $0.20 per 1M input, with the same $1.20 per 1M output. If you're doing heavy prompt-injection testing or bulk processing, Luna's input savings add up. But the output price matching means the real difference shows in how many tokens you burn before you get a usable answer. In that sense, DeepSeek's longer reasoning trace can eat the input advantage fast — and for hacking-style tasks, that's often exactly what you want.
Use case: security vs. general work
This is where the split gets real. Enclave AI called DeepSeek V4.1 Flash its best hacking model, which tracks with DeepSeek's open-weight flexibility and strong instruction-following on adversarial prompts. You can probe it, jailbreak it, and adapt it locally without API gatekeepers. GPT-5.6 Luna is a closed model, so you're renting access — no fine-tuning, no weights, no local ops. That alone makes DeepSeek V4.1 Flash the play for security researchers who need full control. For everyday coding, chat, or structured extraction, Luna's cleaner output tends to need fewer retries, which quietly cancels the price gap.