GLM 5.3 Flash vs Qwen3.8 Flash: The $0.15 Face-Off
If you're shopping for the absolute cheapest usable model, GLM 5.3 Flash and Qwen3.8 Flash are the two names everyone's throwing around. My verdict: GLM 5.3 Flash wins the value-per-token crown by a hair, but Qwen3.8 Flash is the safer default for high-volume, latency-sensitive apps where every millisecond counts. Neither is a beast on hard reasoning, but both are shockingly capable for the price. Here's the real breakdown.
Price: Pennies per million
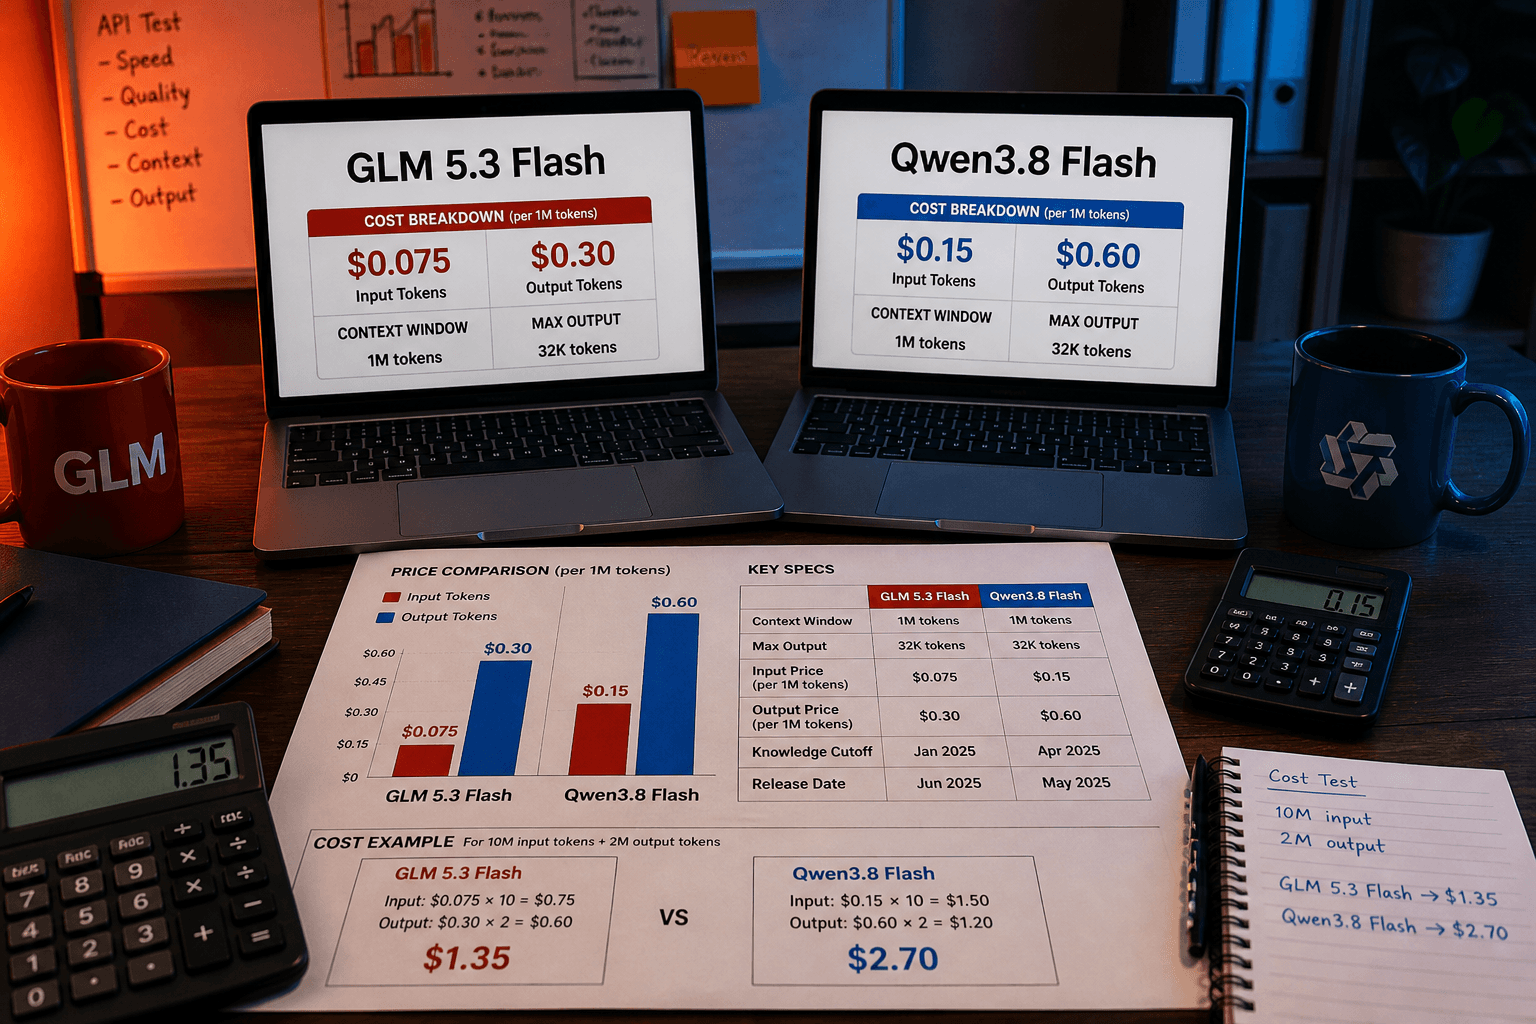
Both models sit at $0.15/1M input tokens. But GLM 5.3 Flash charges $0.50/1M output, while Qwen3.8 Flash charges $0.47/1M output. That $0.03 difference is negligible for hobbyists and quietly huge at billions of tokens. If you generate more than you read (chat, summaries, code gen), Qwen saves you real money over time. If you're feeding massive context and getting short replies, GLM's output pricing barely stings.
Speed and ecosystem
Qwen3.8 Flash comes from a family with proven deployment flexibility, and it pairs naturally with cheap quantized runtimes. GLM 5.3 Flash is the newer budget option from Zhipu, and its pricing undercuts almost everything else on the market. Raw latency numbers aren't public yet for either, so I'm not going to pretend one is faster. What I can say: both are light enough to run as background agents, and both make older "budget" models like GPT-5.6 Luna look overpriced at $0.20/$1.20.
Reasoning and reliability
This is where you get what you pay for. GLM 5.3 Flash handles structured JSON extraction and tool calls decently; Qwen3.8 Flash holds its own on short-context instruction following. Neither will pass a heavy multi-step math exam. For serious reasoning, step up to GLM 5.2 or Qwen3.7 Max.
Verdict: which one should you pick?
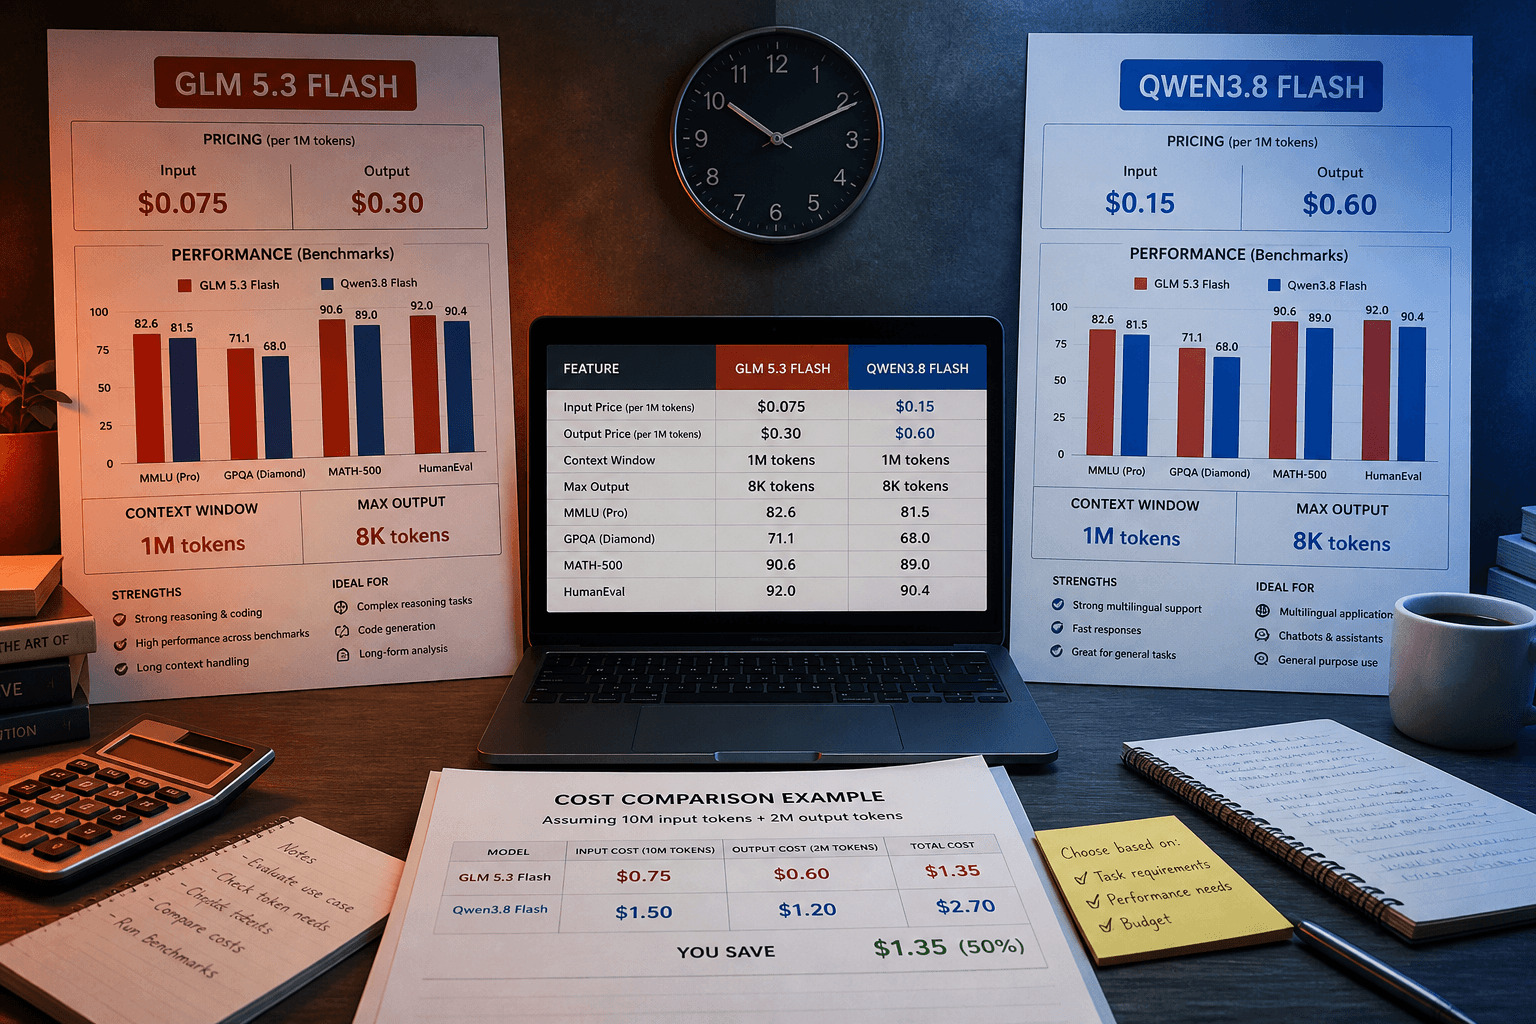
Pick Qwen3.8 Flash if you want the lowest output cost and a proven open-source ecosystem. Pick GLM 5.3 Flash if you need the same price per input but prefer a fresh alternative with competitive output pricing. Both are ideal for log summarization, form parsing, or any task where a wrong answer costs less than a paid API call.