GPT-6 Astra vs Claude Fable 5.1: Same Price, Split Strengths
Same $10/$50 price tag, two very different personalities. GPT-6 Astra is the end-to-end worker, posting 74.1% on DeepSWE, while Claude Fable 5.1 is the reasoning specialist, scoring 66 on the reasoning benchmark to Astra's 61. Pick Astra for real engineering; pick Fable for deep thinking.
Reasoning
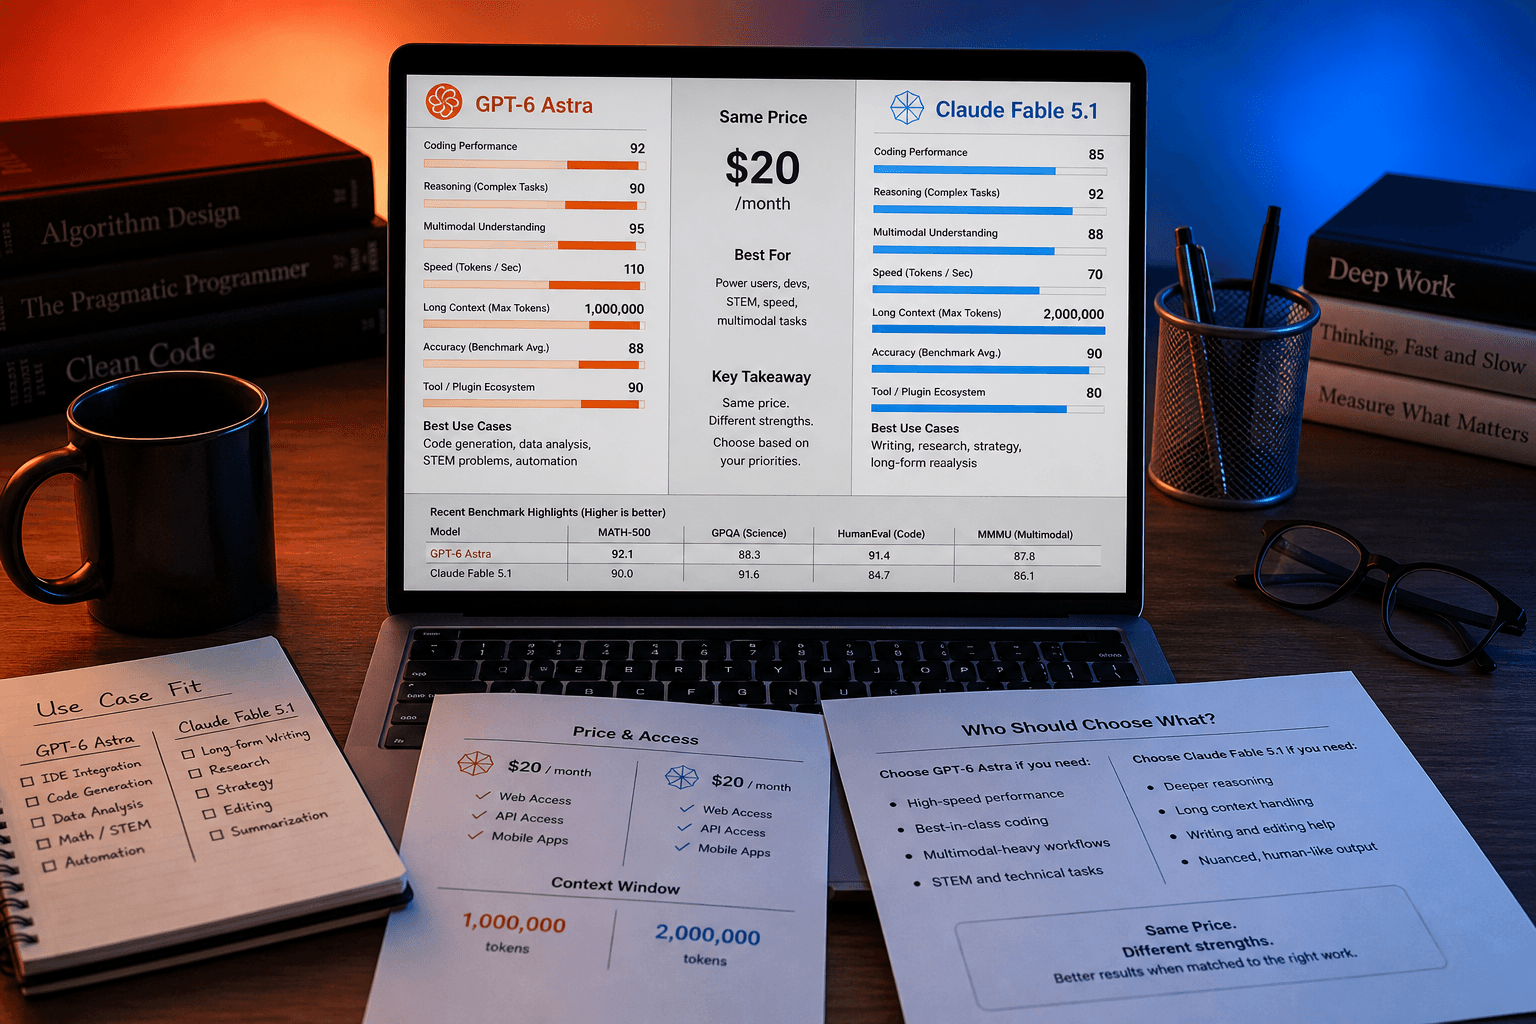
Claude Fable 5.1 owns the reasoning crown right now. A score of 66 on the reasoning benchmark beats GPT-6 Astra's 61, and that gap shows up on logic-heavy tasks where you need the model to think before it writes. If your work is analysis, architecture design, or tricky math-style problem solving, Fable 5.1 gives you more headroom per token.
Getting the job done
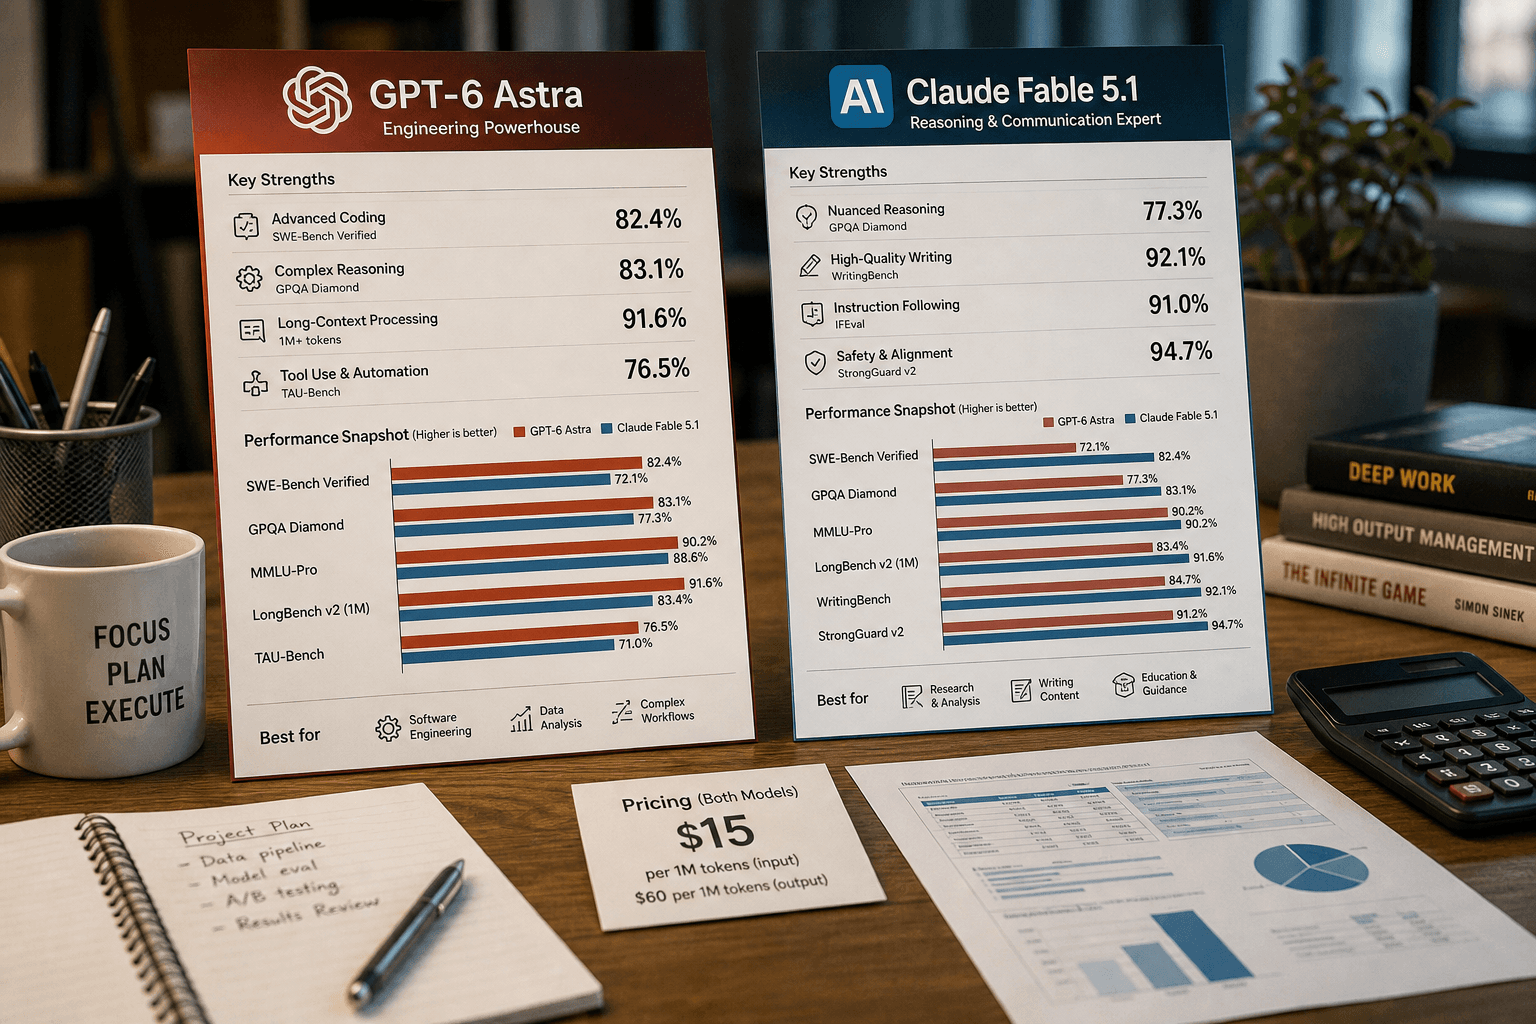
Reasoning scores don't always finish the job. GPT-6 Astra leads on DeepSWE with 74.1%, which measures end-to-end software engineering work — real changes, not just correct-sounding answers. Fable 5.1's raw smarts are impressive, but Astra's higher completion rate suggests fewer retries when the goal is a merged pull request. For production engineering, that's the number that pays rent.
Same price, different value
The pricing is identical: $10.00 per 1M input tokens and $50.00 per 1M output tokens for both models. So the choice isn't about budget — it's about workload. Traditional benchmarks like MMLU and HumanEval have limited standalone value, and the most useful production metric is cost per accepted change. Astra may win on that metric for coding, while Fable 5.1 earns its keep on gnarlier reasoning tasks.
Verdict: which one should you pick?
If you ship software, GPT-6 Astra is the safer default — its DeepSWE lead means more finished work per dollar, even at the same price. If you're doing heavy reasoning, analysis, or planning where the answer matters more than the execution, Claude Fable 5.1 is the better brain. Same cost, different strengths: buy accordingly.