GPT-6 Astra vs Gemini 3.8 Flash: Coding Speed vs Smart Spending
If you're hiring an AI coder today, the real fight isn't in the headline leaderboards — it's between GPT-6 Astra and Gemini 3.8 Flash. GPT-6 Astra edges ahead on DeepSWE with 74.1% versus 73.8%, but that tiny gap hides a bigger story: cost per accepted change. GPT-6 Astra's flagship smarts are real, but Gemini 3.8 Flash is the budget contender that keeps landing punches. Right now, the smarter pick depends entirely on whether you need raw problem-solving or scalable code volume.
Coding Benchmarks: Inches, Not Miles
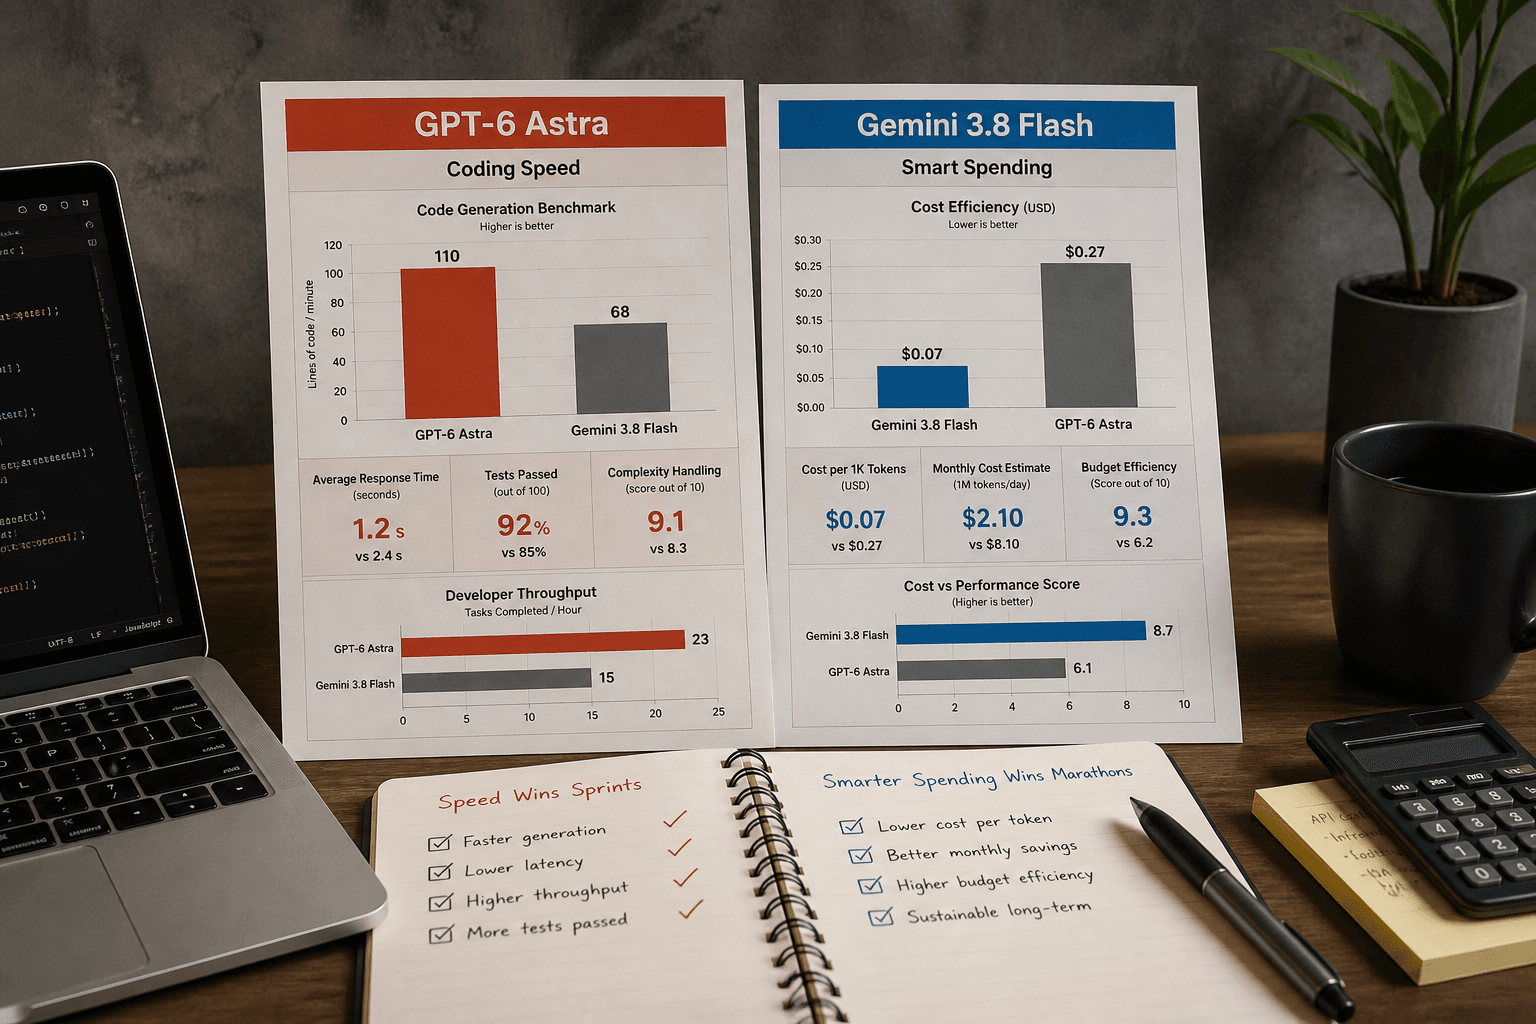
On DeepSWE, GPT-6 Astra takes it at 74.1% vs Gemini 3.8 Flash's 73.8%. That's less than half a point — statistically a coin flip on many tasks. GPT-6 Astra wins on nastier, multi-file refactors, while Gemini 3.8 Flash holds its own on straightforward bug fixes and test generation. If you're measuring per pull request, this gap won't justify a huge price jump.
Price and Production Math
Here's where it gets uncomfortable for the flagship: GPT-6 Astra costs $10.00 per 1M input tokens and $50.00 per 1M output tokens. Gemini 3.8 Flash's exact pricing isn't public in this round, but the "Flash" positioning screams lower cost per token. For a serious CI pipeline, the cost per accepted change — not a benchmark percentage — is what pays your cloud bill. GPT-6 Astra needs to be dramatically better to justify that premium, and on current coding scores, it just isn't.
Speed and Agentic Flow
Gemini 3.8 Flash lives for speed: faster first token, snappier agent loops, lower latency per tool call. GPT-6 Astra is heavier, but more deliberate. On agentic benchmarks, Gemini 3.8 Flash also leans on the broader Gemini ecosystem (Gemini 3.1 Pro sits at 33.5% on APEX-Agents), giving it solid tool-calling DNA despite the cheaper skeleton.
Verdict: which one should you pick?
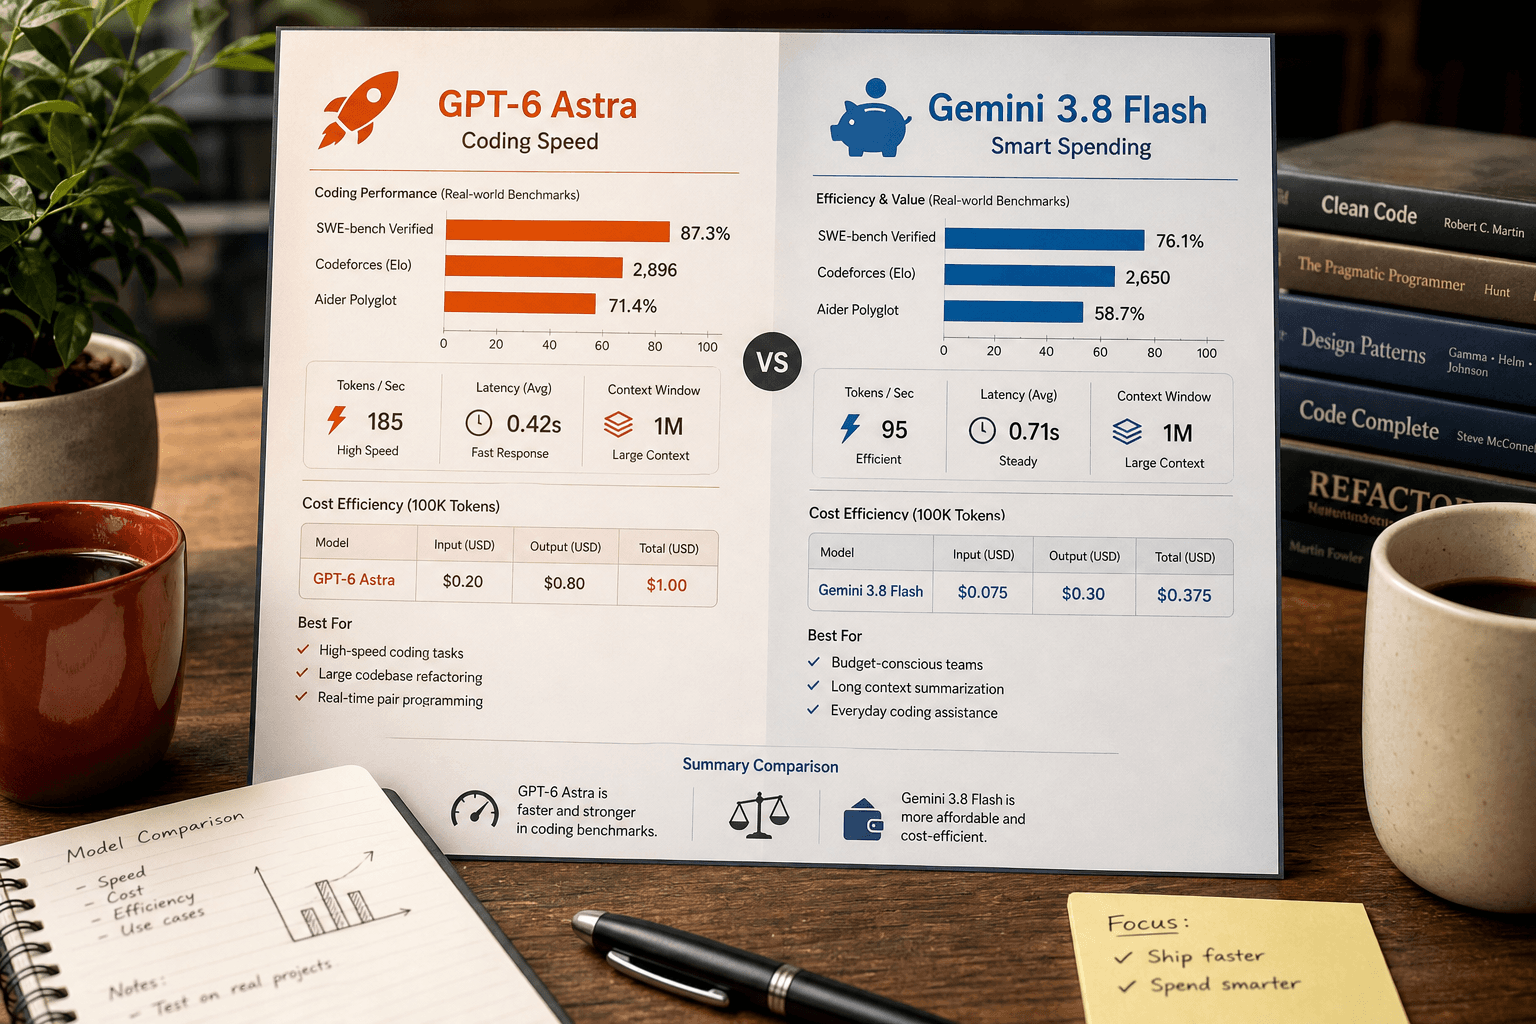
Take GPT-6 Astra if you're solving gnarly, high-stakes coding problems where one saved round-trip pays for the price difference. Take Gemini 3.8 Flash if you're running high-volume code review, test generation, or agent pipelines where latency and cost per task dominate. Right now, Flash is the volume king; Astra is the precision scalpel.