Qwen3-235B vs Gemini 2.5 Pro: Coding vs Reasoning
Verdict: Picking a winner between Qwen3-235B and Gemini 2.5 Pro is like choosing a hammer over a scalpel. Qwen3-235B dominates coding and tool-calling benchmarks, while Gemini 2.5 Pro takes the edge on reasoning and math. If your day is full of repository-wide refactors, go Qwen. If you're wrestling with proofs or agentic workflows, Gemini wins. Plain as that.
Coding and Tool Use
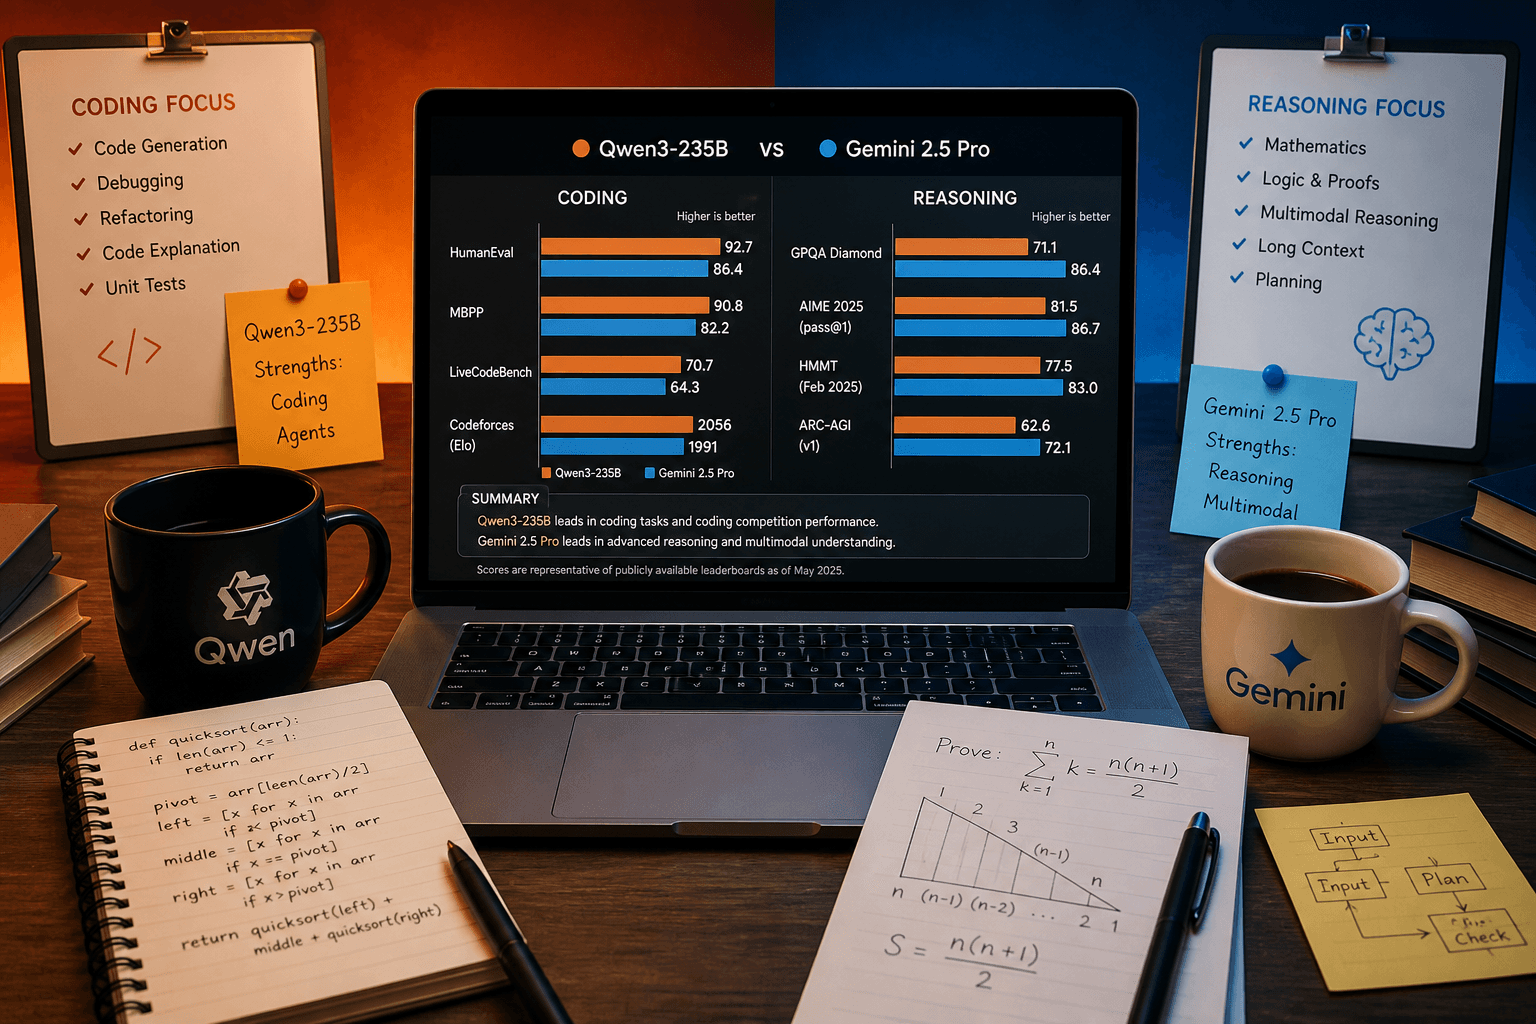
Qwen3-235B doesn't mess around when the task is writing or fixing code. It leads on CodeForces ELO Rating, BFCL, and LiveCodeBench v5. That means it handles function calls and competitive programming problems better than Gemini 2.5 Pro. For AI agents that need to grab the right tool and actually use it, Qwen's BFCL dominance is the stat to watch.
Reasoning and Math
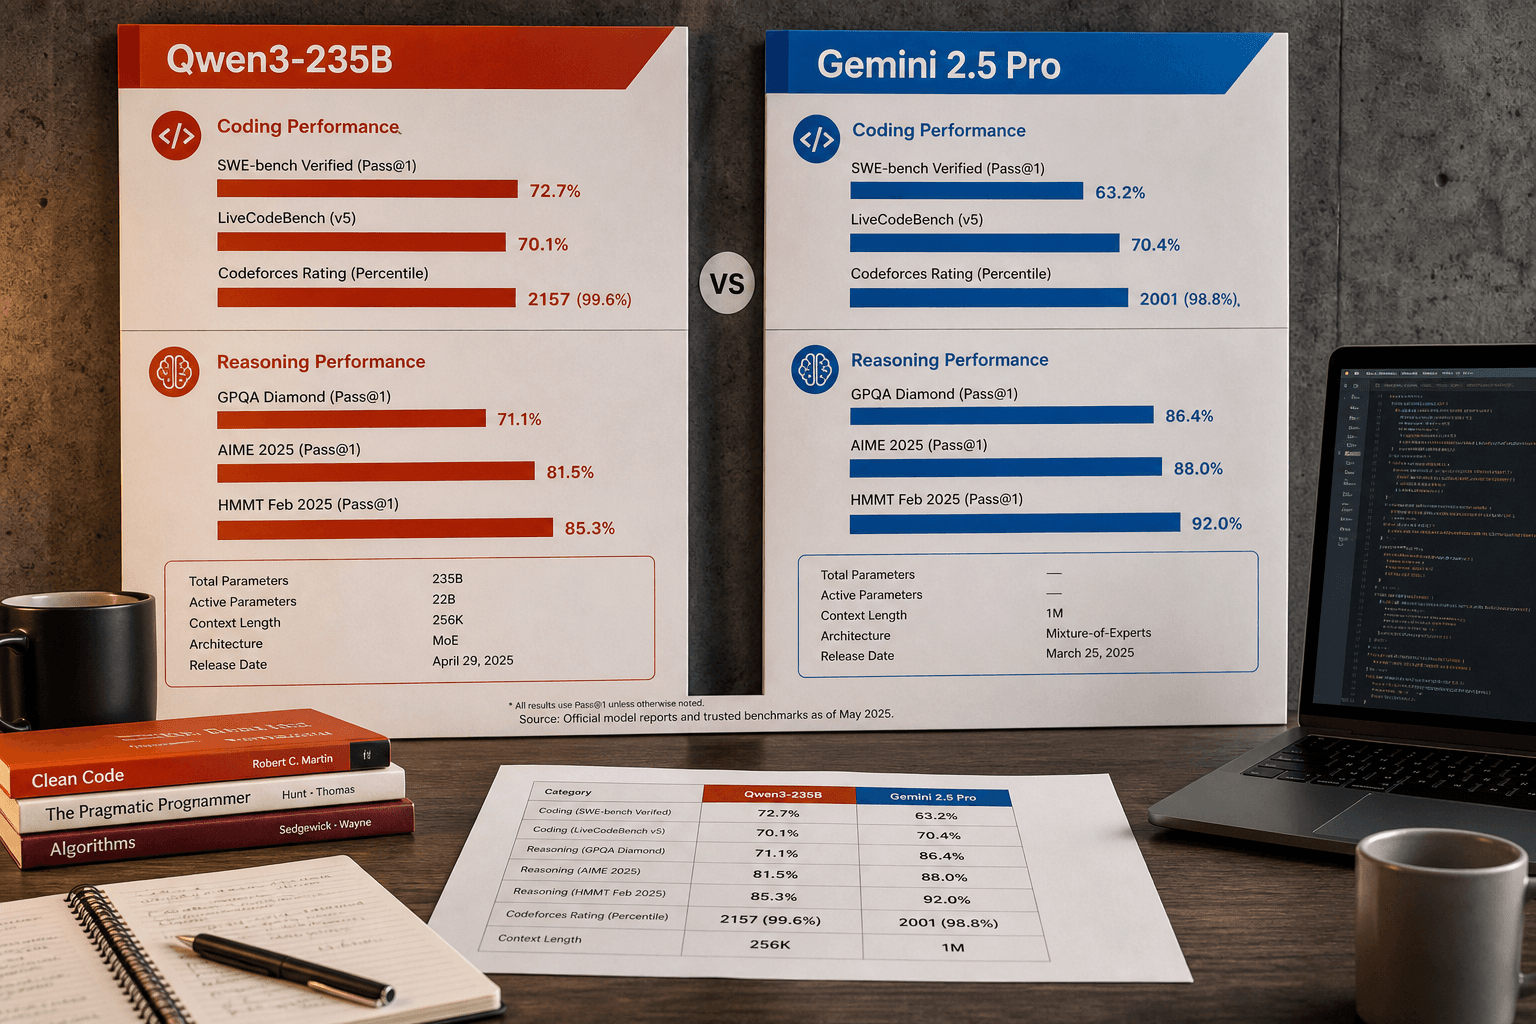
Gemini 2.5 Pro hits back hard on ArenaHard, AIME, and MultilF. Aider Pass@2 also goes to Gemini, which matters if you do a lot of iterative code editing with an assistant. The AIME result is the big one: tougher math reasoning, Gemini handles it more consistently. Qwen's own agentic chops don't translate to better puzzle-solving here.
Which Models Suit Whom
The pattern is clear. Qwen3-235B fits developers who want a workhorse for structured coding tasks, especially where tool selection matters. Gemini 2.5 Pro suits researchers, math-heavy users, and anyone running agent loops that demand broad reasoning over raw speed. Neither model is a dud; they just have different strengths.
Verdict: which one should you pick?
Pick Qwen3-235B if your work is mostly code generation, API calls, and benchmark-driven engineering. Pick Gemini 2.5 Pro if you need abstract reasoning, math, and careful multi-step edits. You'll get better results by matching the model to the task than by arguing about which one is "smarter."