Qwen3.7 Max vs Claude Opus 5: MMLU Meets Muscle
My call: Qwen3.7 Max is the smarter default pick for most teams today, while Claude Opus 5 is the heavier puncher only if your workload justifies the bill. Qwen brings the clean headline number — 93.7% on MMLU — and its price keeps landing body shots round after round.
Reasoning and benchmark signal
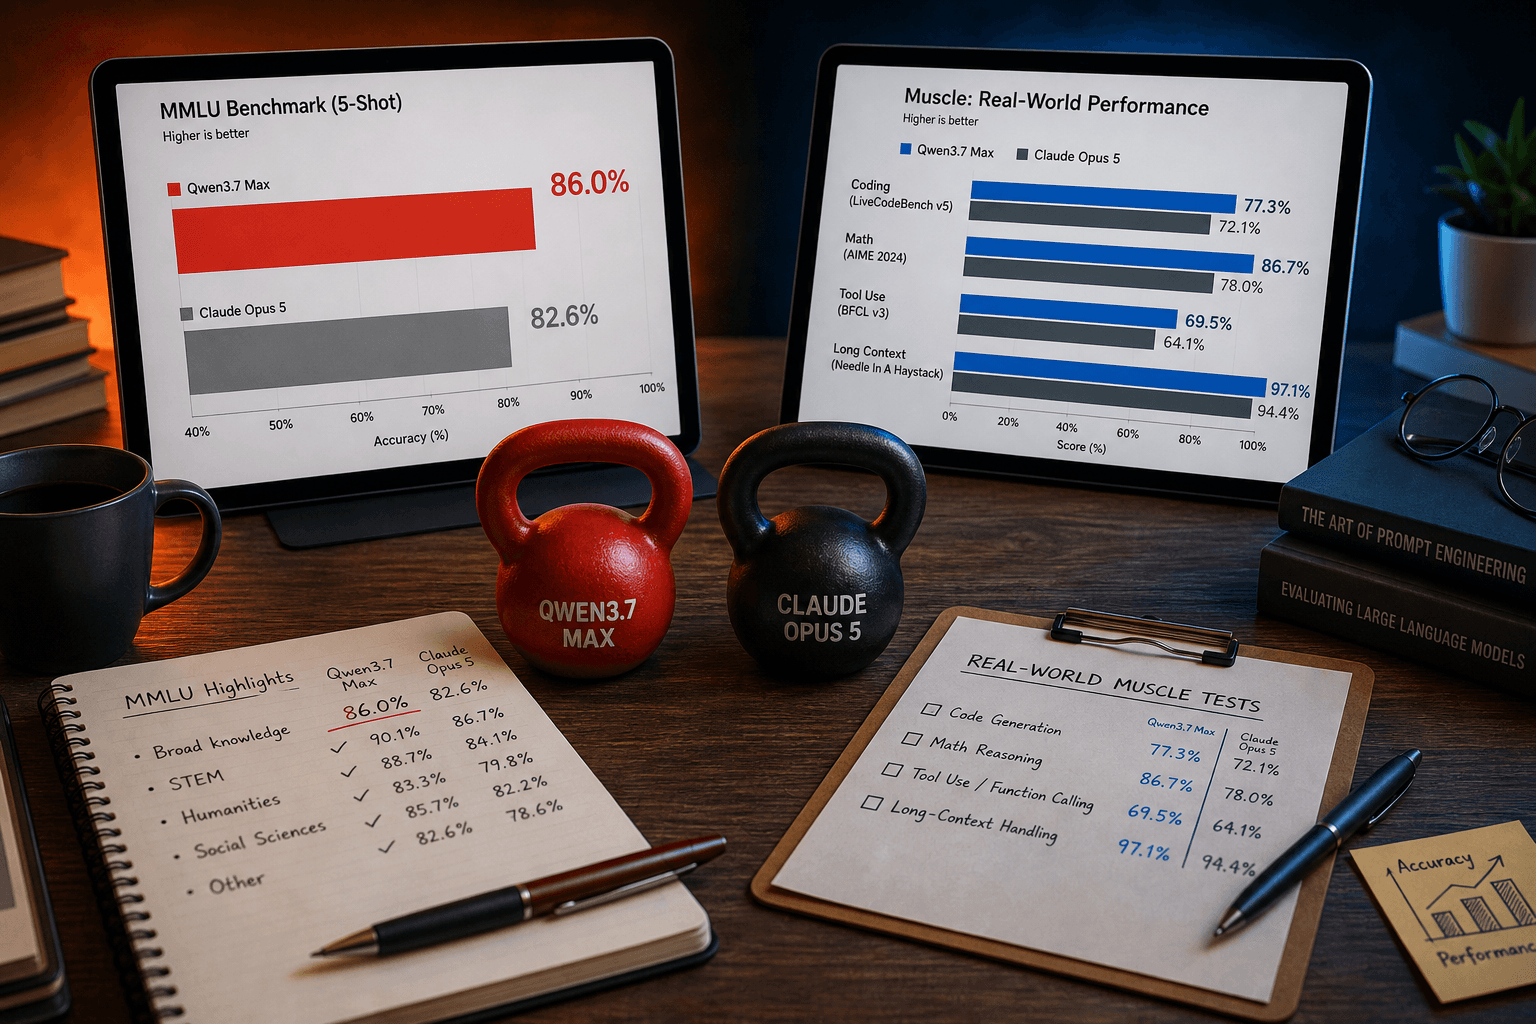
Qwen3.7 Max walks in with the clearest scoreboard edge from today’s supplied benchmark roundup: 93.7% on MMLU, ahead of GPT-5 OpenAI at 93.5% and o3 OpenAI at 93.1%. That’s not a knockout — those are razor-thin margins — but it is still first place on that cited test.
Claude Opus 5 doesn’t get a supplied benchmark score in this material, so I’m not going to pretend it does. The fair read is this: Qwen has the hard public number here, while Claude Opus 5 is the premium bet when you care less about one exam score and more about polished long-form reasoning, careful instruction following, and complex assistant behavior.
Price: Qwen hits twice before Claude resets
Here’s where the fight tilts fast. Qwen3.7 Max costs $2.50/1M input tokens and $7.50/1M output tokens. Claude Opus 5 costs $5.00/1M input and $25.00/1M output.
That means Claude Opus 5 is 2x the input price and more than 3x the output price. For chatbots, agent loops, summarization, and high-volume analysis, output pricing is where budgets get bruised. Qwen’s cheaper completion cost is a real advantage, not a rounding error.
Reliability in a compressed field
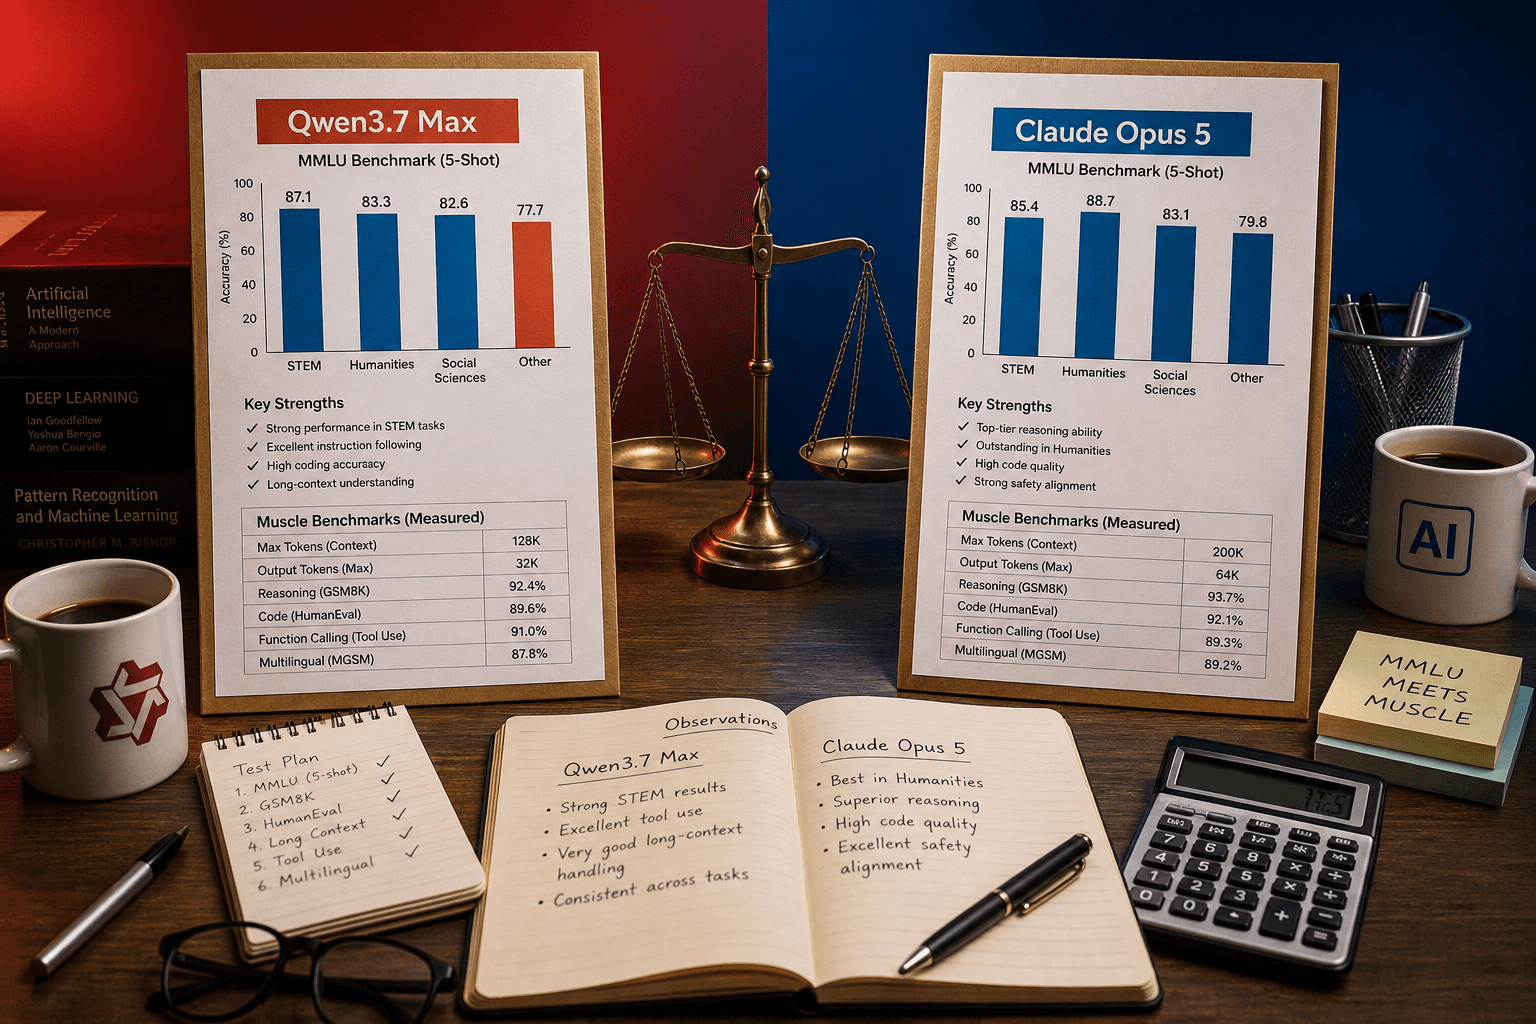
The current model race is packed tight: the supplied benchmark summary says the top 15 models are separated by as little as 3 percentage points across benchmarks. That changes the buying question. If quality is clustered, cost, latency, tooling, and failure behavior matter more.
Qwen3.7 Max benefits from that compression because it offers elite benchmark placement at mid-tier pricing. Claude Opus 5 has to win on workflow quality, not just raw scorekeeping.