Qwen3.7 Max vs Google Gemini 3.1 Pro Preview: Exam or Logic
Verdict from the bell: Qwen3.7 Max is the sharper pick for knowledge-heavy work, while Google Gemini 3.1 Pro Preview is the better bet when reasoning depth matters. The split is clean: Qwen lands the highest cited MMLU score at 93.7%, but Gemini owns the reasoning lane in today’s benchmark chatter.
Knowledge and benchmark muscle
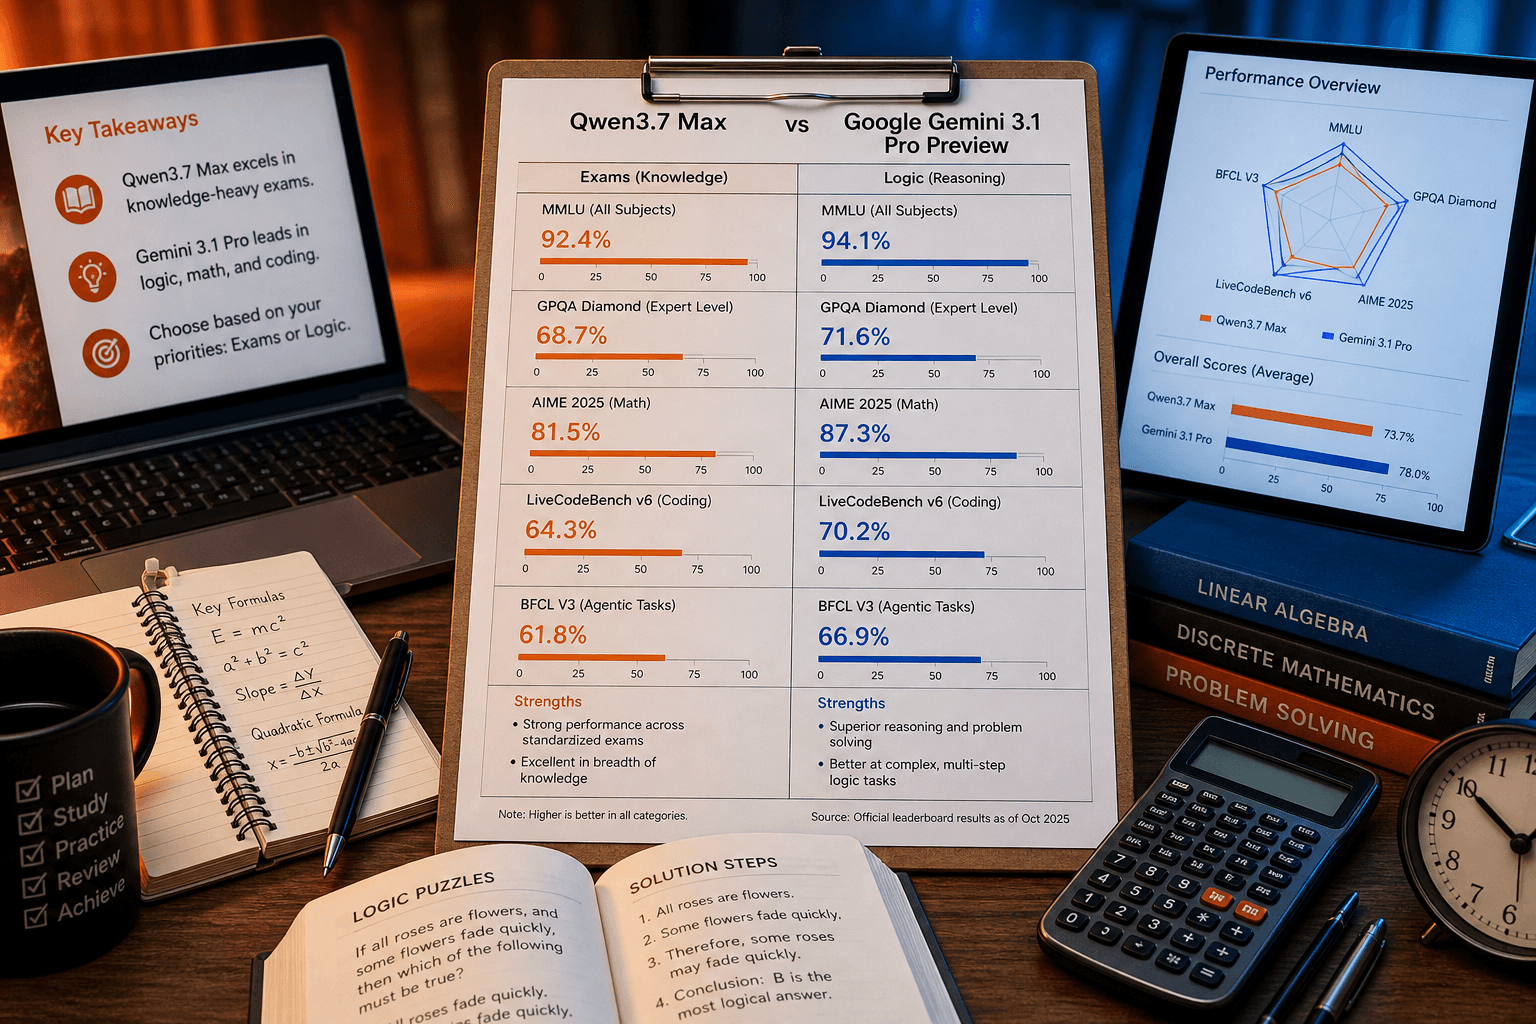
Qwen3.7 Max comes out swinging on MMLU, where the current material has it leading at 93.7%. That’s a real punch, especially with GPT-5 OpenAI listed close behind at 93.5% and o3 OpenAI at 93.1%.
Gemini 3.1 Pro Preview isn’t framed as the MMLU champ here. Its headline strength is reasoning, where the material says Gemini 3.1 Pro leads. So if your workload is fact recall, exams, structured QA, or broad academic coverage, Qwen has the cleaner scoreboard argument.
Reasoning versus cost
Now Gemini answers with body shots. At $2.00/1M input tokens and $12.00/1M output tokens, Google Gemini 3.1 Pro Preview is cheaper than Qwen3.7 Max, which is priced at $2.50/1M input and $7.50/1M output.
That pricing split is sneaky. Qwen costs more to feed, but less to generate from. Gemini is cheaper on input-heavy tasks, while Qwen can look better when output volume climbs. If you’re running long prompts with shorter answers, Gemini has the cleaner cost profile. If you’re generating longer responses, Qwen’s $7.50 output rate hits back hard.
Market context and reliability
The broader field is tight. The material says the performance gap across the top 15 models can be as little as 3 percentage points, with Arena Elo led by Anthropic at 1,503, then xAI at 1,495, Google at 1,494, OpenAI at 1,481, Alibaba at 1,449, and DeepSeek at 1,424.
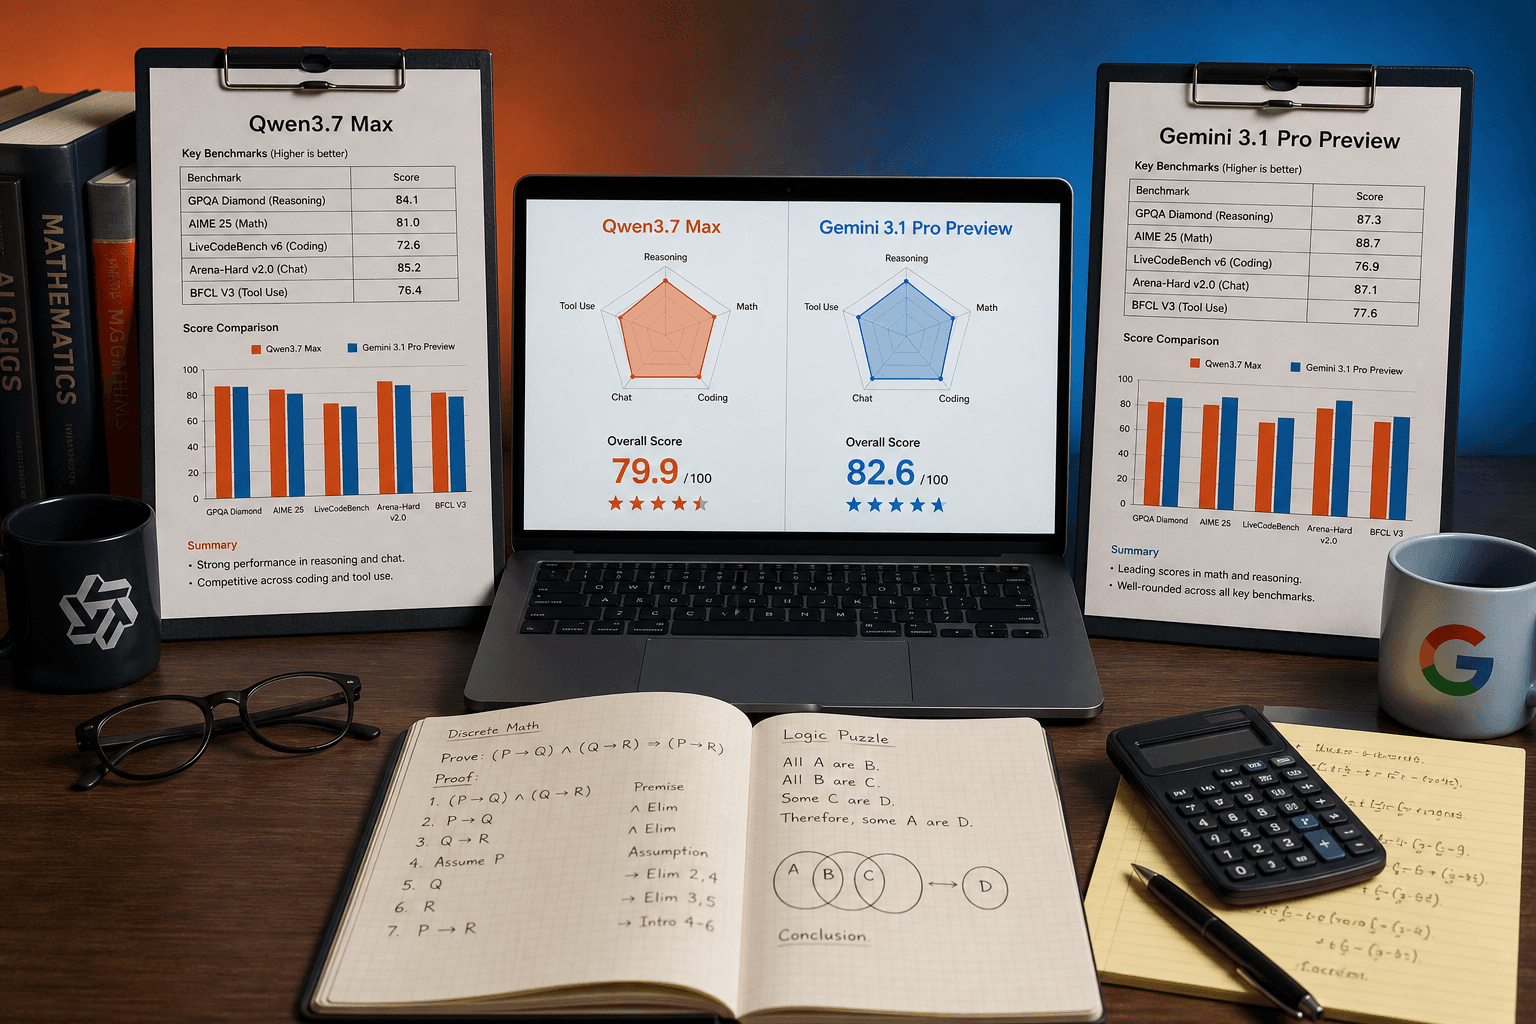
That means neither model gets a free coronation. Qwen’s MMLU crown matters, but Gemini’s reasoning lead matters just as much depending on the job.