xAI Grok 4.5 vs Anthropic Claude Opus 5: Value Fight
My call: xAI Grok 4.5 is the better default buy today, while Anthropic Claude Opus 5 is the safer premium pick when answer quality matters more than spend. The fight is close at the top, but the price card is not close, and that changes the round scoring.
Price: Grok 4.5 lands the cleanest body shot
Grok 4.5 is listed at $2.00/1M input tokens and $6.00/1M output tokens. Claude Opus 5 is $5.00/1M input and $25.00/1M output. That means Opus costs 2.5x more on input and more than 4x more on output.
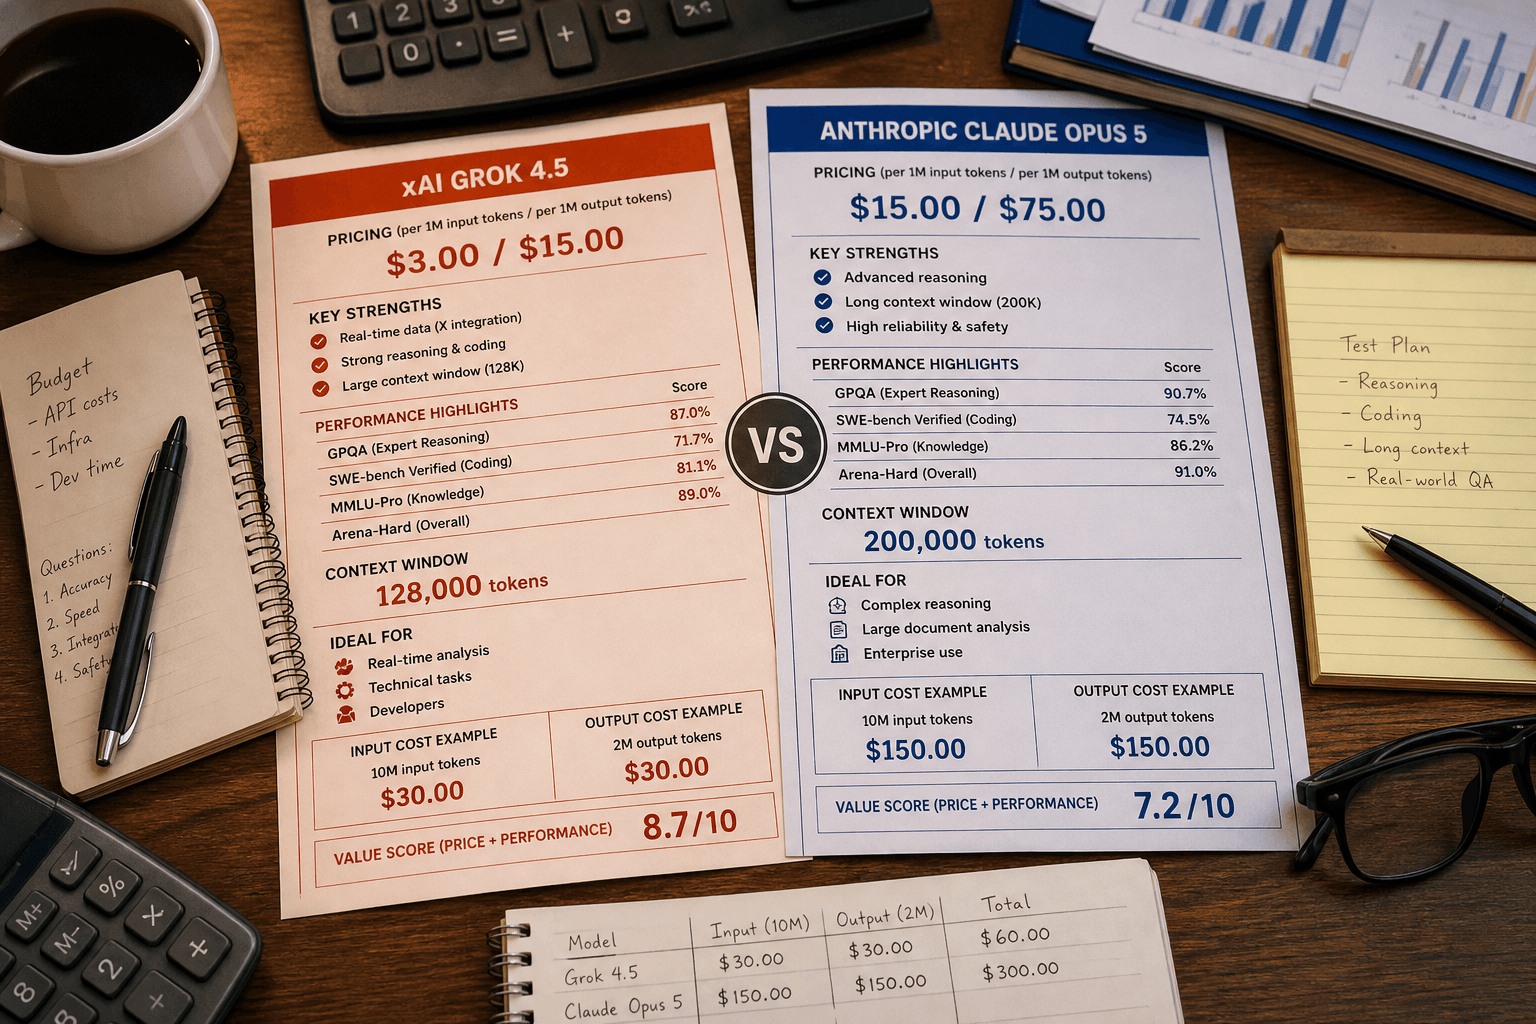
If you’re running support agents, summarizers, search assistants, or high-volume internal tools, that gap is brutal. At 100M output tokens, Grok 4.5 costs $600; Claude Opus 5 costs $2,500. That’s not a rounding error. That’s the bell ringing.
Top-tier quality: Opus still has the premium chin
The live ranking picture says the frontier is crowded: Anthropic leads Arena Elo at 1,503, with xAI right behind at 1,495. That’s an 8-point spread, not a wipeout. The broader field is tight too, with the top 15 models separated by as little as 3 percentage points across benchmarks.
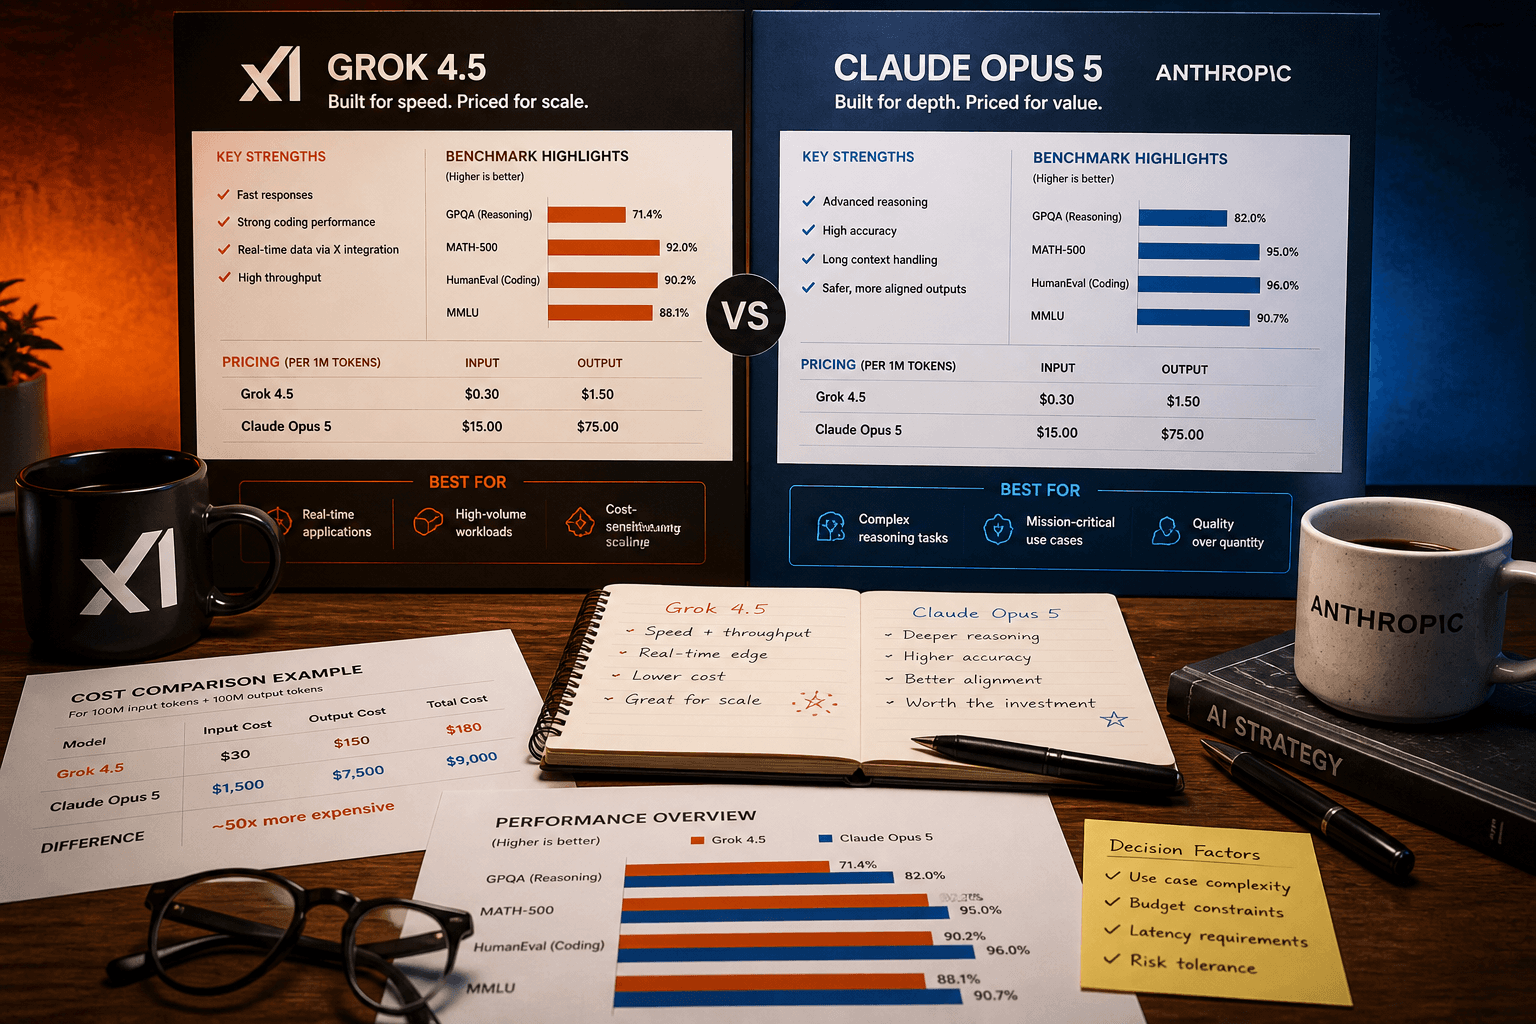
So no, Grok 4.5 isn’t some bargain-bin bruiser. But Claude Opus 5 earns its premium case when you need steadier long-form synthesis, careful agent planning, and fewer “close enough” answers in high-stakes workflows.
Coding and agent work: pick your risk profile
The current chatter around coding is hot because Grok 4 and Claude Opus 4.6 are both cited among coding leaders. For Grok 4.5 vs Opus 5, that points to a real split: Grok is the aggressive value play; Opus is the quality-control play.
If your pipeline has tests, retries, and human review, Grok’s price wins rounds fast. If failures are expensive, Opus buys you more confidence.